In this guide 6 sections
Clean data in a fixed order. Profile the records and back them up first, then standardise formats, flag duplicates for review, apply written merge rules and reconcile the result against the original. Then fix the entry point that let the mess in, since a cleanup without that repair simply starts to decay again on the day it finishes.
Profile the Data and Keep an Authorised Baseline First
Take a coworking operator whose member list has lived in a booking app, a WhatsApp group and a paper desk register for two years. The same member appears under a personal email in one place and a company email in another, so a headcount of members quickly turns into guesswork. Profile before touching anything. Count the rows, the rows missing a required field, the likely duplicates and the date range the data spans, so the project has a measurable before and after.
Take a backup next. A full, dated copy taken before any edit, with the data owner’s sign-off that it is the correct starting point, is the only thing that makes the cleanup reversible. Skip this step under time pressure and any wrong merge becomes permanent, however confident the person doing the cleanup feels on the day.
Standardise Formats, Validate Fields, Then Identify Duplicates
Standardise before you look for duplicates. Inconsistent formatting hides duplicates, because “St Louis” and “Saint Louis” will not match as one city until the spelling is aligned across every record. Bring dates, phone numbers, addresses and category labels into one format first, using a short written list of the accepted patterns that everyone doing the cleanup can follow.
Validation tests each column against a rule. A phone number should have the right digit count, a tax registration number should match its known pattern, and a date of birth should not fall in the future. Only then is matching reliable. Match on a shared identifier such as a phone number or tax registration number, and where none exists use a reviewed fuzzy match on name and address.
Define Explicit Merge Rules and Keep a Trail
Every merge needs a survivor rule. When two confirmed duplicates disagree, the surviving value is usually the most recently updated field or the one from the system designated authoritative for that field. Without a rule, whichever record was processed last wins, and that is not a decision anyone made, so nobody can justify the result later.
Write the rule first. Settled case by case, similar conflicts get resolved differently depending on who is cleaning that day, whereas a short fixed rule set stays defensible.
- Map both original record IDs to the surviving merged record, so any single merge can be traced back and undone without searching old spreadsheets.
- Log which fields came from which original record, the date of each merge and the name of whoever approved it, in a sheet kept apart from the data.
- Archive pre-merge records, never delete them.
Reconcile the Cleaned Output Against the Source
Compare totals after cleaning. Check record counts, summed order values and customer counts in the cleaned file against the backup, and the drop in records must equal the confirmed merges. A gap means records vanished. If the totals do not match, records were lost or altered somewhere in the process, and the cause has to be found before the cleaned file replaces the original.
Reviews need a different reviewer. Someone other than the person who did the cleaning should run and review this reconciliation, which is a basic safeguard against one person’s blind spots.
Prevent the Same Mess From Recurring
Cleanup treats the symptom. The mess returns from the same entry points: free-text fields instead of dropdowns, no duplicate warning when a new customer is created, and no required-field check on entry.
Close the entry point. A mandatory field or a warning that a near-identical record already exists is often enough, because without either the same project returns at the same cost.
Data-cleaning checklist and log
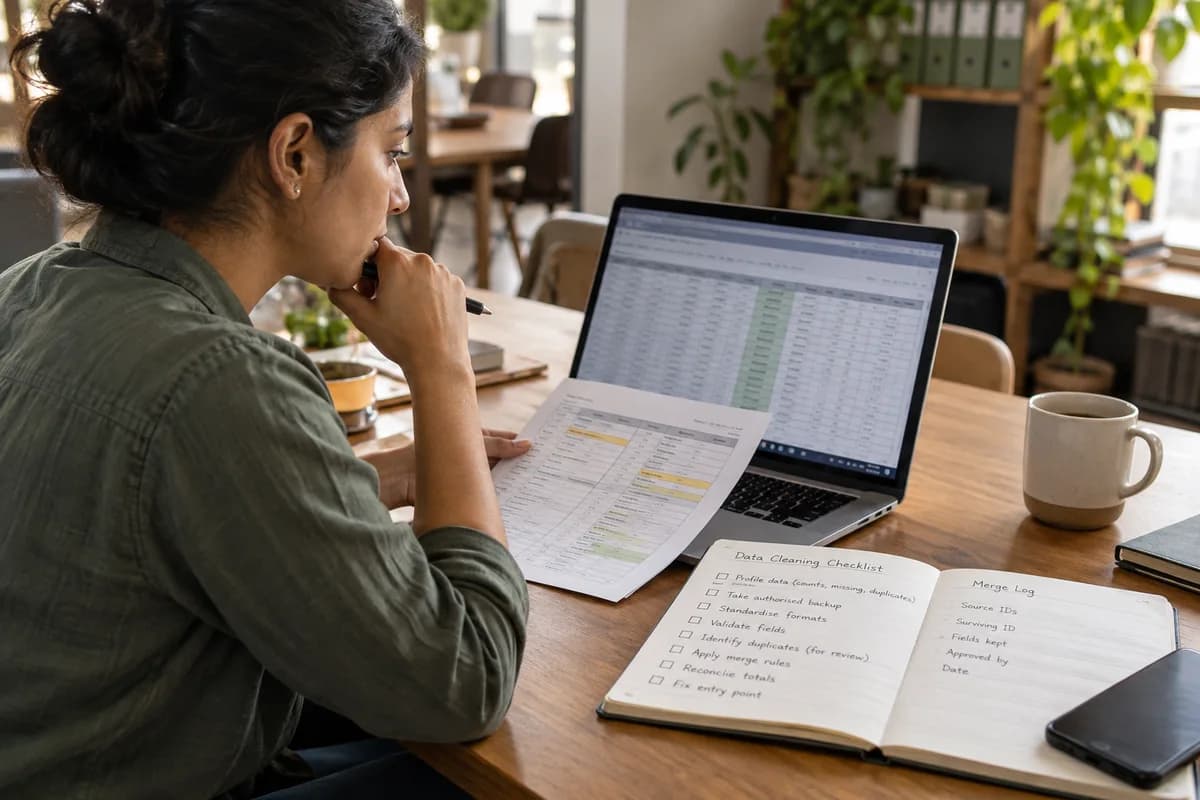
A step-ordered checklist covering profiling, backup, standardisation, validation, duplicate identification, merge rules and reconciliation, paired with a log template recording each merge decision, its source records and the approver.
Open a blank worksheet to printQuestions owners ask
Should duplicates be deleted automatically?
No, they should not. A record that only looked like a duplicate can be destroyed by auto-deletion, so flag likely pairs for review, apply the merge rule once confirmed, and archive the originals.
How do we keep an audit trail of changes?
Log every single merge. Record both original record IDs, the fields kept from each source, the approver and the date, and store that log apart from the cleaned data so it survives edits.
Who should approve the backup?
The data owner signs off. That person confirms the backup is the correct starting point, since a cleanup run on the wrong snapshot can erase the only copy of a recent correction.