In this guide 6 sections
Most businesses do not need a live second region. Start with the cost of an hour of downtime, then check data residency rules. If a single region with multiple zones and a restore you have actually tested meets the target, stop there. Add a second region only when that arithmetic fails.
Put a number on one hour of downtime
Ask finance and support for three figures: lost orders per hour, idle staff per hour, and any service credits written into customer contracts. Add them up. That total caps what a second region could ever be worth.
Now ask how long a full regional outage has really lasted. Get dates. Providers publish incident histories on their status pages. Whole-region failures are rare. Most outages are narrower, such as one managed service, one zone or one bad deploy.
A customer asking about availability usually wants a stated recovery target, not a topology diagram. Write the target in two numbers. How much data you can lose, and how long you can be down.
- Recovery point objective in minutes of data
- Recovery time objective in hours of downtime
- Contract credits owed per breach
- Peak trading hours that raise the cost
Check where the data is allowed to live
Residency can settle the question before cost does. A health provider, a bank or a public-sector buyer may require records to stay inside one country, so a second region abroad becomes a breach, not a safeguard.
Read the data processing agreement you signed with each customer. Look for named countries, subprocessor lists and clauses about replication. Backups count as data, so a copy stored abroad can break the same clause.
Some providers offer two regions inside one country. Others do not. Check the region list before you promise anything.
Single region done properly covers a lot
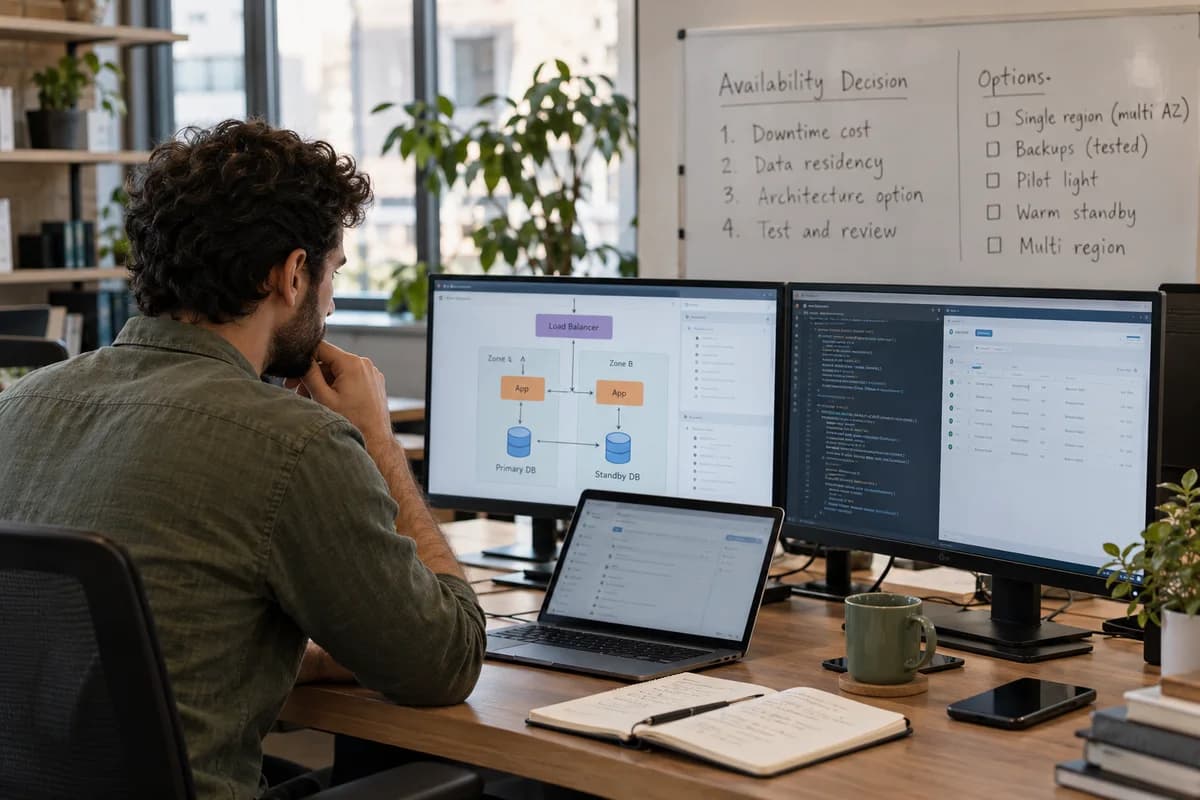
Spread the application across at least two availability zones. Run the database with a standby replica in a second zone and automatic failover, then put the load balancer in front of both. That setup survives a data centre fire, a power fault or a failed rack.
Then add backups that leave the failure domain. Snapshots go to a bucket with versioning, object lock and, where residency allows, a copy in another region. Cold storage in a second region costs far less than running a second live stack.
A backup you have never restored is a hope. Schedule a restore into a scratch environment every quarter. Time it. Record the minutes, then compare the result with your recovery target.
- Application servers in two or more zones
- Database standby with automatic failover
- Versioned, locked backup bucket
- Infrastructure defined as code in git
- Quarterly restore drill with a timed log
The middle options before a full second region
Pilot light keeps the database replicating to a second region while the servers stay switched off. On failure you start them from stored machine images and repoint DNS. Recovery takes hours. Running cost stays small.
Warm standby runs a reduced copy of the stack, always on and taking no traffic, so it recovers in minutes. Active-active serves users from both regions at once, and it brings hard problems of its own: write conflicts, session handling, cache coherence and doubled operations work.
Pick the lowest rung that meets the target. Climbing a rung needs a written reason, such as a contract clause or a measured outage cost.
Decide, write it down, and test the choice
Put the decision on one page. State the downtime cost, the residency limits, the chosen rung and the failure it does not cover. Share it with the customer who asked. Honest limits build more trust than a diagram of two regions that nobody has failed over.
Run a game day. Switch off a zone during working hours with the team watching and see what breaks, then do the same for a database failover. Fix what you find before you pay for more infrastructure.
Review the choice once a year, or when a large contract lands. This week, find your last restore test date and run one if it is older than three months.
Availability decision sheet
A one-page worksheet in four blocks. Block one lists downtime cost per hour with rows for lost orders, idle staff and contract credits. Block two records residency limits by customer, country and clause. Block three holds a ladder of five rungs from single zone to active-active, with recovery point, recovery time and monthly run cost for each. Block four notes the chosen rung, the owner and the next restore drill date.
Open a blank worksheet to printQuestions owners ask
Is multi region deployment overkill for a small SaaS product?
Usually, yes. Multiple zones in one region plus a tested restore cover most real failures. A second region earns its cost when a contract demands it or when an hour of downtime costs more than the extra infrastructure.
How often does a whole cloud region fail?
Rarely. Check the incident history on your provider’s status page for the region you use. Most outages hit a single service or zone, or come from your own bad release, which a second region would copy.
What is the difference between pilot light and warm standby?
Pilot light replicates data but keeps servers off until you need them. Warm standby keeps a small running copy of the stack. The first is cheaper and slower to recover. The second recovers in minutes.
How do I answer a customer who asks if we are multi region?
Give your recovery point and recovery time targets, explain the zones and backups behind them, and share the date of your last restore test. That answers the real concern better than a yes or no.