In this guide 6 sections
Pick by symptom. A slow filter on a big table needs an index. The same expensive read repeated all day needs a Redis cache. Heavy reports that slow down order entry need a read replica. Each fix adds a cost: slower writes, stale data or another server to maintain.
Read the symptom before you pick a tool
Open the slow query log or your APM trace and find the one statement behind the slow page. Do this first. Guessing leads to a Redis server bolted onto a query that only needed one index.
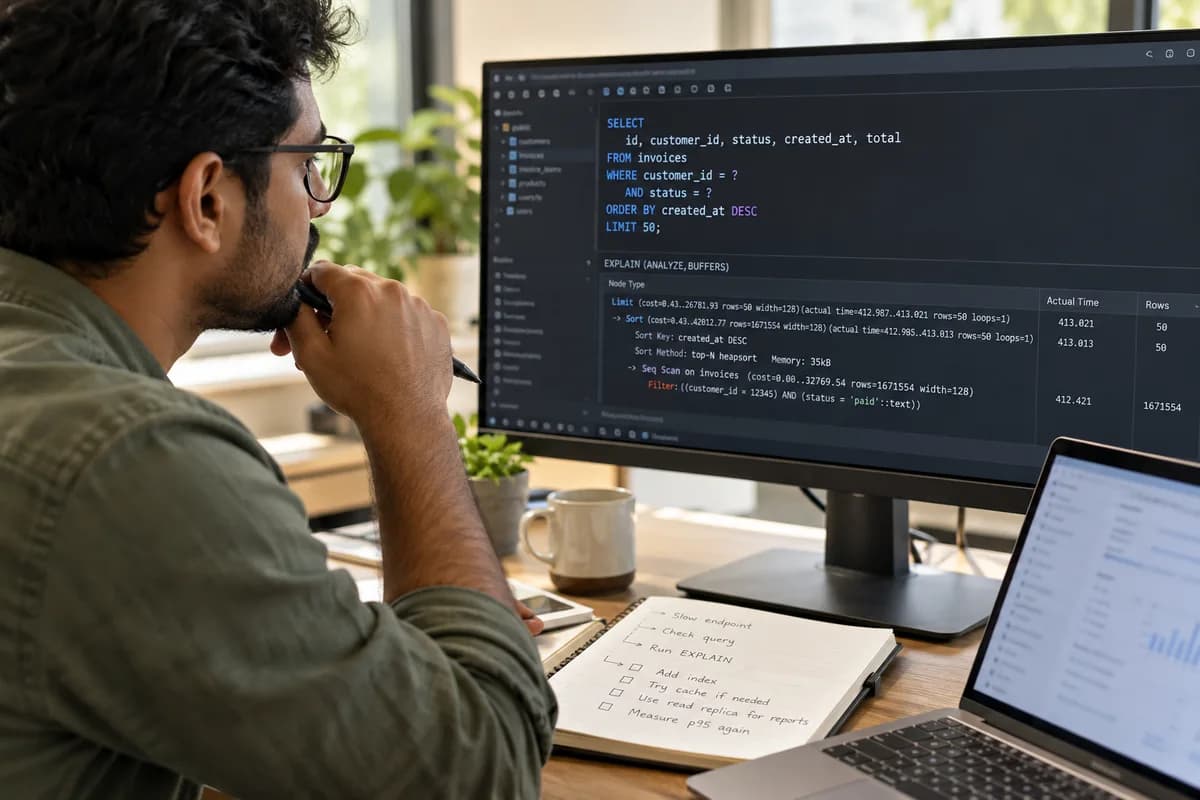
Run EXPLAIN on that statement. If you see a sequential scan over a table with hundreds of thousands of rows, you have an indexing problem. If the plan looks sensible but the same result is fetched thousands of times an hour, you have a repetition problem. If the plan is fine and the page is slow only when the finance team runs month-end exports, you have a contention problem.
- Sequential scan on a filtered column points to an index
- Identical query repeated per page view points to a cache
- Slowdowns that match report schedules point to a replica
- A slow join across many tables may need a rewrite instead
An index fixes the slow filter
A B-tree index on the column in your WHERE clause lets PostgreSQL or MySQL jump to matching rows instead of reading the whole table. Searching invoices by customer_id or status is the classic case, and it is the cheapest fix and usually the first one to try.
The cost lands on writes. Every INSERT and UPDATE must also maintain each index, so a table with eight of them slows down on bulk imports. Unused indexes also eat disk. Check pg_stat_user_indexes or the sys schema and drop the ones nobody reads.
Composite indexes need care. Column order matters. A query that filters on the second column of a composite B-tree alone will not use it.
A cache fixes the repeated expensive read
Redis holds the result in memory, so the next thousand requests skip the database entirely. It suits data that is costly to build and changes rarely, such as a product catalogue with price tiers, a dashboard total or a permissions lookup. Set a TTL on every key.
The cost is stale data. Someone updates a price, and the cache still serves the old one until the key expires or you delete it. Decide who owns invalidation before you write the first SET. A cache also hides a slow query rather than curing it, so the first request after a restart still hurts.
Never cache what must be exact. Stock counts at checkout and payment status are the usual offenders.
- Catalogue and price list lookups
- Session data and permission checks
- Aggregated dashboard figures refreshed on a timer
- Rate limit counters
A read replica fixes report load
A replica is a second copy of the database that receives changes from the primary and serves read-only queries. Point your BI tool, CSV exports and scheduled reports at it, and order entry on the primary then stops competing with a twenty-minute GROUP BY.
Replication lag is the price. The replica may trail the primary by a second or by minutes during a heavy write burst. A user who saves a record and is redirected to a page reading from the replica can briefly see the old version. Keep read-after-write screens on the primary.
You also pay for another server, its backups and its monitoring, and it does nothing for a slow single query because the replica runs the same plan.
Apply one fix, measure, then decide on the next
Make a single change per test run. Record the p95 response time of the affected endpoint before, add the index, and record it again under the same load. Then try the cache only if the page is still slow.
Many teams end up with all three, in order: index first, cache second, replica third, because skipping ahead means paying upkeep for a problem you never confirmed.
Write the result next to the ticket. Today, pull your slowest endpoint from the logs. Run EXPLAIN on its main query.
Slow page triage sheet
A one-page worksheet listing each slow endpoint on its own line. Columns are endpoint, query text, EXPLAIN result, rows scanned, calls per hour, reader of the data, staleness allowed, chosen fix and p95 before and after. A closing block records who owns cache invalidation and the replication lag limit.
Open a blank worksheet to printQuestions owners ask
Should I add a Redis cache before an index?
Rarely. An index is cheaper to run and cannot serve stale data, whereas a cache in front of an unindexed query only hides the cost until the key expires.
Can a read replica replace caching?
No. A replica spreads load but every request still runs the query. A cache skips the query entirely for repeated reads.
How stale can cached data be?
Ask the business. A dashboard total can trail by a minute, while a stock count at checkout cannot trail at all. Set the TTL from that answer.
Do too many indexes hurt?
Yes. Each one slows INSERT and UPDATE statements and uses disk. Review index usage statistics every quarter and drop the unused ones.