In this guide 6 sections
Only a few causes explain most failures. Secrets go missing on forked pull requests, the runner carries a different Node or PHP version, no dependency cache exists, two deploys overlap, or the included minutes run out. Read the log before changing anything.
Why are my secrets empty on a pull request?
The restriction is deliberate. Workflows triggered by a pull request from a fork do not receive repository secrets, because otherwise anyone could open a pull request that prints your server key.
The symptom is an empty variable and a step that fails with a missing credential or a blank value, so check first whether the branch lives in a fork. Then gate secret steps behind a merge.
Avoid pull_request_target as a shortcut. It runs with your secrets against code that nobody has reviewed, so a hostile pull request could read every credential the workflow can reach.
Why does it pass on my laptop and fail on the runner?
The runner starts clean every time. It carries its own default Node or PHP version, which may differ from yours, so pin the version with setup-node or setup-php and match production.
Case sensitivity is another trap. A file named Logo.png imported as logo.png works on macOS, breaks on Linux, and a missing lockfile lets npm install newer packages than you tested.
Fallout hides the cause. Read the first failing step, not the last one, because the later red lines in the log are usually fallout from that early failure.
- Node or PHP version not pinned
- Lockfile not committed
- File name case mismatch
- Environment variable set locally only
- Test database not started as a service
Why is the run slow every single time?
Cold installs waste minutes. Turn on the cache built into setup-node, or use actions/cache keyed on the hash of package-lock.json or composer.lock, so unchanged dependencies are restored instead of downloaded.
Check the checkout step too. A full history clone of a large repository takes time that a shallow fetch avoids, and independent jobs such as lint and tests should run in parallel.
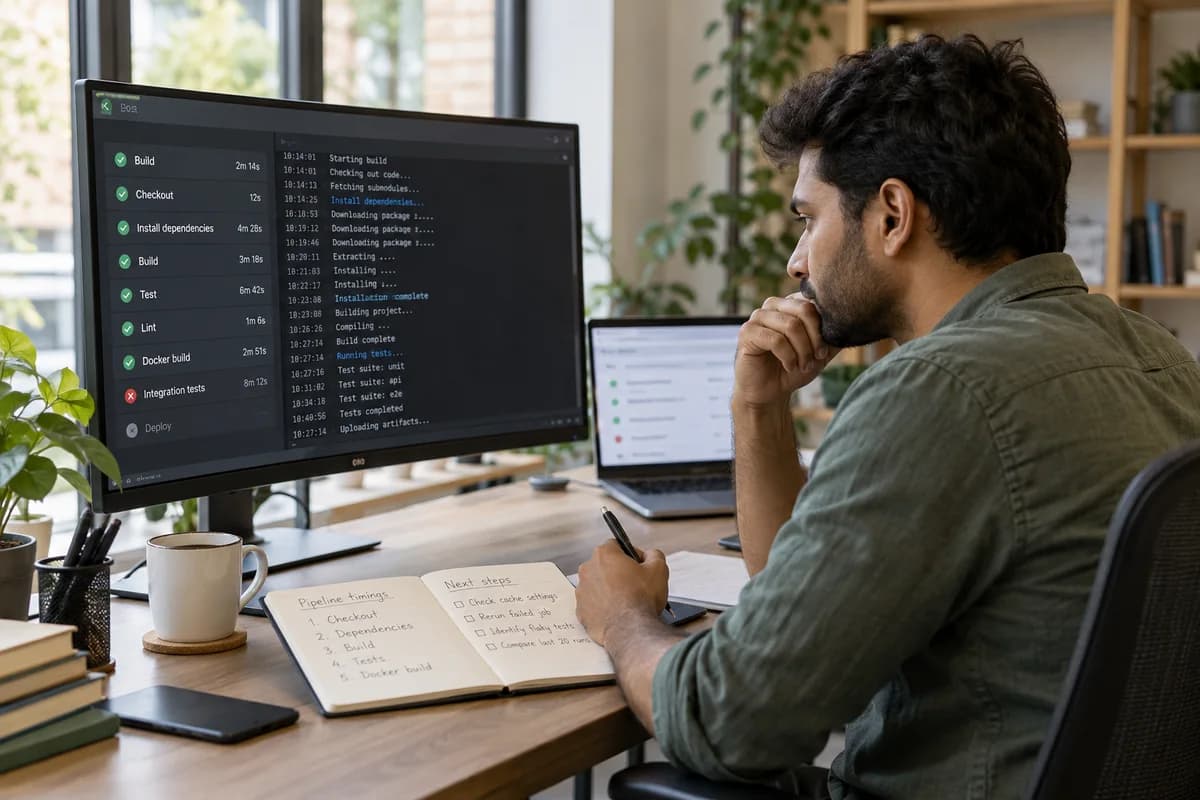
Compare the timing column between runs. If the npm install step dropped from minutes to seconds once the cache warmed, you have found the culprit, and the same check works for every other step.
- Dependency cache keyed on the lockfile
- Shallow checkout with fetch-depth set low
- Lint and tests running in parallel
- Docker layers reused between runs
Why do deploys collide or the token get refused?
Two merges in quick succession can start two deploys that write to the same server folder, so one finishes half a release and the other overwrites it. Make the deploys queue. A concurrency group with cancel-in-progress set to false lets the running release finish while the next one waits its turn behind it.
The GITHUB_TOKEN has limited permissions by default. A step that creates a release, pushes a tag or comments on a pull request fails with a 403 until the workflow grants contents: write.
Grant only what the job needs. Nothing broader belongs there.
How do I read the log and spot a billing limit?
Expand each step and find the first red line, then re-run the job with debug logging by setting the secret ACTIONS_STEP_DEBUG to true. It prints every command the runner executed.
A job that never starts is different. It may be waiting for a runner label that no machine carries, or the account may have run out of included minutes, which the billing page shows under usage.
Keep notes on each cause. Add them to the repository readme this week, so the next engineer on call starts from a written answer instead of guessing at a failing deploy.
Failed run triage sheet
One page, four columns. Each row pairs a symptom with its likely cause, how to confirm it and the fix, covering empty secrets, version mismatch, missing cache and overlapping deploys. Rows also cover tokens and billing. A last block holds the link to the failing run, plus the maintainer of the workflow file and the date of the last change to it.
Open a blank worksheet to printQuestions owners ask
Why does my workflow not start at all?
Check the trigger and the branch filter first, then confirm the file sits in .github/workflows and parses as valid YAML, because a typo there stops the run. A job stuck in the queue is different, usually a runner label that no machine carries or an account with no included minutes left.
Are self-hosted runners faster?
Yes, often, because caches stay warm. You then own patching, cleanup and security, and an untrusted pull request must never run on a runner that can reach your internal network or deploy keys.
How do I stop deploys overwriting each other?
Name a concurrency group after the environment, leave cancel-in-progress off for deploy jobs, and let each later release wait while the running one finishes. Queued deploys beat overwritten ones.
Can I re-run just the failed job?
Yes, failed jobs only. Use it for flaky network steps, such as a registry download that timed out, but fix the cause if the same job fails twice in a row.