In this guide 6 sections
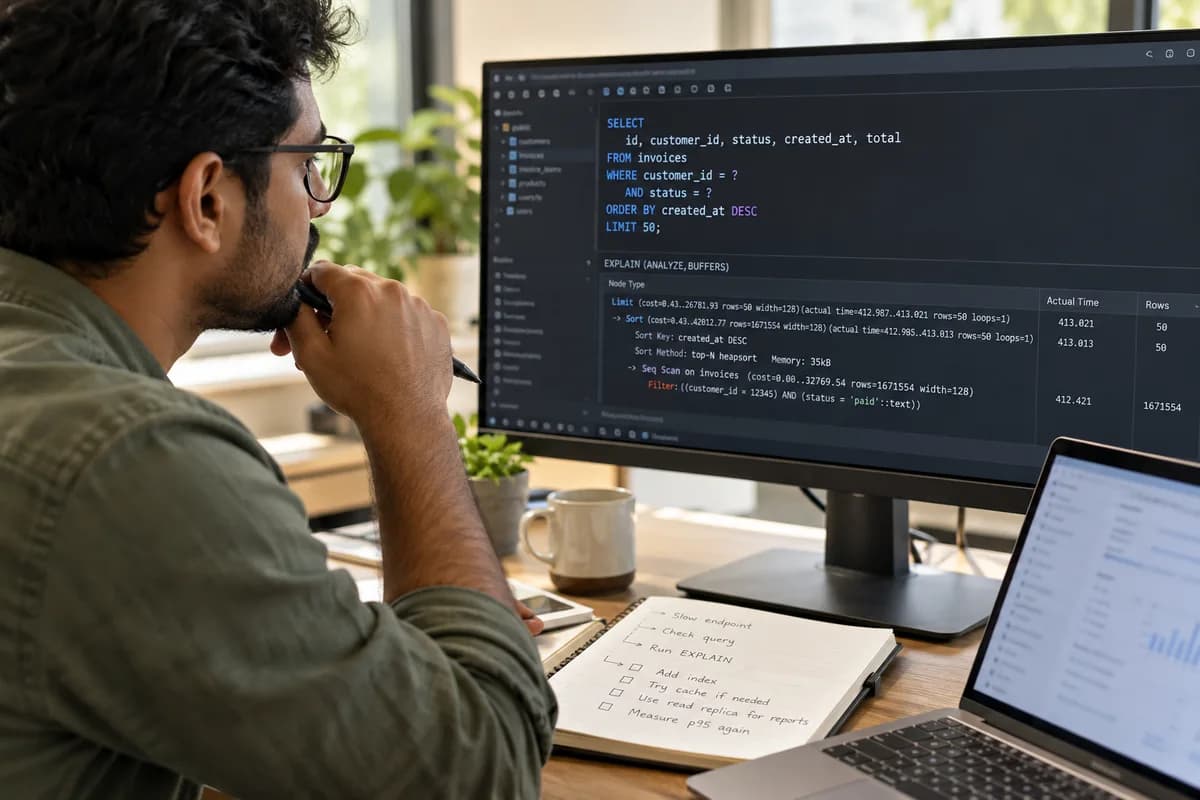
Run EXPLAIN (ANALYZE, BUFFERS) on the slow query and look for the node with the largest actual time. Check for sequential scans on big tables, row estimates far from actual rows, sorts that spill to disk, and repeated queries from the app.
Run the plan on the real query
Copy the exact statement from your logs, including the parameter values. Put EXPLAIN (ANALYZE, BUFFERS) in front of it and run it in psql against a copy of production data. A tiny test database will show a different plan.
ANALYZE really executes the statement. For an UPDATE or DELETE, wrap it in BEGIN and finish with ROLLBACK. Otherwise you will change data while you investigate.
The output is a tree. Each node shows an estimated cost and rows, then actual time and actual rows. Read from the innermost, most indented node outward.
- Use the real parameter values
- Run on a restored copy of production data
- Wrap writes in BEGIN and ROLLBACK
- Save the plan text to compare after each change
Find the node that eats the time
Look at actual time on each node, then multiply by loops. A node showing two milliseconds that runs forty thousand times is your problem. The headline total hides that.
Compare rows against actual rows. When the planner expects ten rows and finds two hundred thousand, it picks a plan built for the wrong size. That mismatch is the most useful clue in the whole output.
Check the Buffers line too. Many shared reads mean data came from disk, not memory. Hits mean the table was already cached. Run the query twice and compare, since the first run warms the cache.
Read the usual suspects
A Seq Scan on a large table, with a Filter line removing most rows, usually means a missing index on the filtered column. A Seq Scan on a small table is fine and often faster.
An index that exists but goes unused is a different story. Causes include a function wrapped around the column, a type mismatch between the column and the parameter, or a leading wildcard in a LIKE pattern.
A Sort node showing Sort Method: external merge Disk means the sort did not fit in work_mem. Raise it for that session first, test, then decide if a composite index could return rows already ordered.
- Seq Scan with a large Rows Removed by Filter
- Index Scan never chosen despite an index
- Sort Method external merge on disk
- Nested Loop with a huge outer row count
- Hash Join batches above one
Separate database problems from app problems
Sometimes every query is quick and the page is still slow. Turn on log_min_duration_statement, or use the pg_stat_statements extension, and count calls. If one page fires three hundred near identical SELECT statements, the app has an N+1 pattern.
The ORM loads a list of orders, then asks for each customer one by one. Fix it with a join, or load the related rows in one query using a list of ids.
No index will rescue that pattern. The cost is round trips, not scanning. Each trip pays for network latency, parsing and planning, however fast the lookup itself runs.
Fix in this order and measure each step
First, remove the repeated queries from the app. Second, add or correct one index and run ANALYZE on the table so statistics refresh. Third, rewrite the query if it pulls columns or rows the page never shows. Last, tune memory settings.
Make a single change per test and keep the before and after plans. An index that speeds one report can slow inserts on a busy table.
Tonight, pick your slowest list page, capture its plan and write down the three largest actual times. That note is your starting point.
Slow query diagnosis sheet
Every slow query gets a line on this single sheet. Columns hold the page name, SQL text, time before, the costliest node, estimated against actual rows, the fix tried, time after and date. A tick list covers Seq Scan, unused index, disk sort and N+1.
Open a blank worksheet to printQuestions owners ask
Is it safe to run EXPLAIN ANALYZE on production?
Reads are usually fine, though they use real resources. For writes, use a transaction you roll back, or better, a restored copy of the database.
Why does PostgreSQL ignore my index?
Common causes are a function applied to the column, mismatched types, a leading wildcard, or a table so small that scanning it is cheaper. Stale statistics can also mislead the planner.
What does Rows Removed by Filter tell me?
It counts rows read and then thrown away. A large number next to a small result suggests an index on the filtered column would let the database skip them.
How do I spot an N+1 problem?
Count statements per page request. Enable pg_stat_statements and look for one query with a very high call count. Your ORM’s debug log shows the same pattern.