In this guide 6 sections
Untested software fails in front of customers instead of a tester, as a broken checkout, a wrong invoice total or a crash on a common phone. Testing cannot remove every bug. It finds the defects most likely to cost money, trust or compliance, and it finds them while the fix is still a quick edit rather than an apology.
What an untested journey costs a business
Testing is often treated as a formality after the real work of building is done, yet an untested journey is a business risk nobody has priced. Autofill may break checkout. A report rounds a tax figure wrongly, a permissions bug lets one branch read another’s customer list, and none of it shows until a customer or auditor hits it.
The cost is rarely just the fix. It includes the refund, the support call, the customer who does not come back and the manager who goes back to the spreadsheet the system was meant to replace. Cost is lowest before launch. That is why the cost of finding a defect rises the later it is found, from a quick edit in testing to a long cleanup after launch.
The four kinds of checks a launch needs
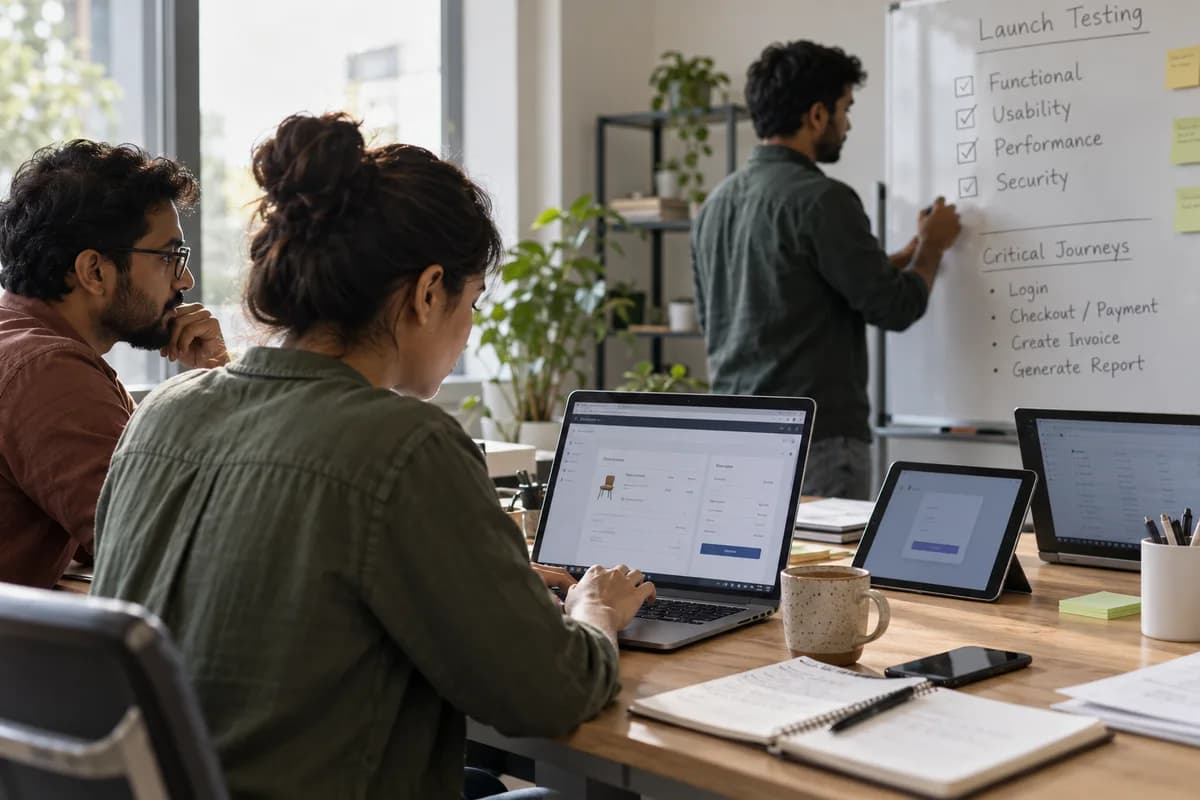
“Testing” is often used as if it were one activity, but a launch needs four distinct kinds of checking, and skipping any one leaves a specific risk uncovered. Functional testing asks whether a feature does what it should, so it checks that the invoice total calculates correctly and that a placed order reaches the kitchen screen. Usability testing asks whether a real employee can finish that journey on the first attempt, in glare on a small screen, without a manual and without phoning the developer.
Performance testing asks whether the same journey survives ten people using it at once, or a report pulled over three years of data not three days, without turning sluggish. Security testing asks whether someone can make the journey do something it should not, such as reading another customer’s order by changing a number in the address bar. Functional checks alone are not enough.
- Functional: does the feature do what it should
- Usability: can a first-time user finish without help
- Performance: does it hold up with real volume
- Security: can it be made to do something it should not
Testing the journeys that matter most, with realistic data
Few small businesses have the time to test every path with equal depth, and trying to is usually why testing gets cut under deadline pressure. Rank the journeys by damage. A failed login is bad, a failed payment is worse, a failed payroll run is worse again, and testing effort should follow that ranking rather than build order.
Realistic data catches more. A tidy test account misses bugs that appear only with an ampersand in a company name, an uppercase code typed in lowercase or a list of four hundred products. An apostrophe can break a surname. A retailer that tests billing with one sample invoice watches it pass, then fail on the first real invoice that carries a discount and a partial return together. The test data never held that mix.
Deciding what blocks a release and what can ship
Every round of testing turns up defects, and they do not all deserve the same reaction, so sorting them by severity keeps the argument short. A critical defect blocks a core journey or corrupts data, and it stops the release until it is fixed and the journey is checked again from the start. Lower severities can wait.
Release acceptance is the decision about which severities are acceptable to launch with, and it should be made deliberately by someone with authority, not by default because nobody asked. Known minor defects can ship on purpose. They must never ship by accident. Log each one against a person and a deadline in the next update, so the list of accepted defects does not quietly become the backlog nobody reads.
- Critical: blocks a core journey or damages data, so stop the release
- Major: breaks something important but has a workaround, such as a report that truncates long names, so fix it on a dated plan
- Minor: cosmetic, such as wrapping text on one screen or a flickering icon, so log it for the next update
Why “fully tested” is a misleading promise
No amount of testing proves software has no bugs, because it shows only that the specific things checked worked under the specific conditions checked. That is no reason to skip testing. It is a reason to say what testing covered and what it did not, and to keep watching for issues after go-live rather than stopping there.
The goal is lower risk. Catch the defects that would have cost money, write down what there was no time to check, and prepare for what slips through with monitoring and a rollback path. Keep a hotfix routine ready.
Business-risk-to-test mapping
A table lists business risks down the left, namely lost revenue, wrong financial figures, data exposed to the wrong role and a journey customers abandon. Four test types run across the top. Each cell marks whether functional, usability, performance or security testing would catch that risk, so a business sees at once which risks its current plan leaves uncovered.
Open a blank worksheet to printQuestions owners ask
Can developers test their own work?
They should test their code, but a developer knows how a feature was meant to work and rarely tries a unicode name, a backspace mid-form or a rotated screen. Independent eyes catch different defects.
Does passing tests mean there are no bugs?
No. Passing tests confirm the scenarios checked worked and say nothing about scenarios nobody thought to check, so a clean pass is evidence that known risks were addressed, not proof.
How long should testing take before launch?
It depends on how many journeys carry real risk, so rank them, agree what blocks a release, and stop when critical and major defects are fixed or knowingly accepted. The calendar is a poor judge.