Document Intelligence and OCR for Forms and Delivery Notes
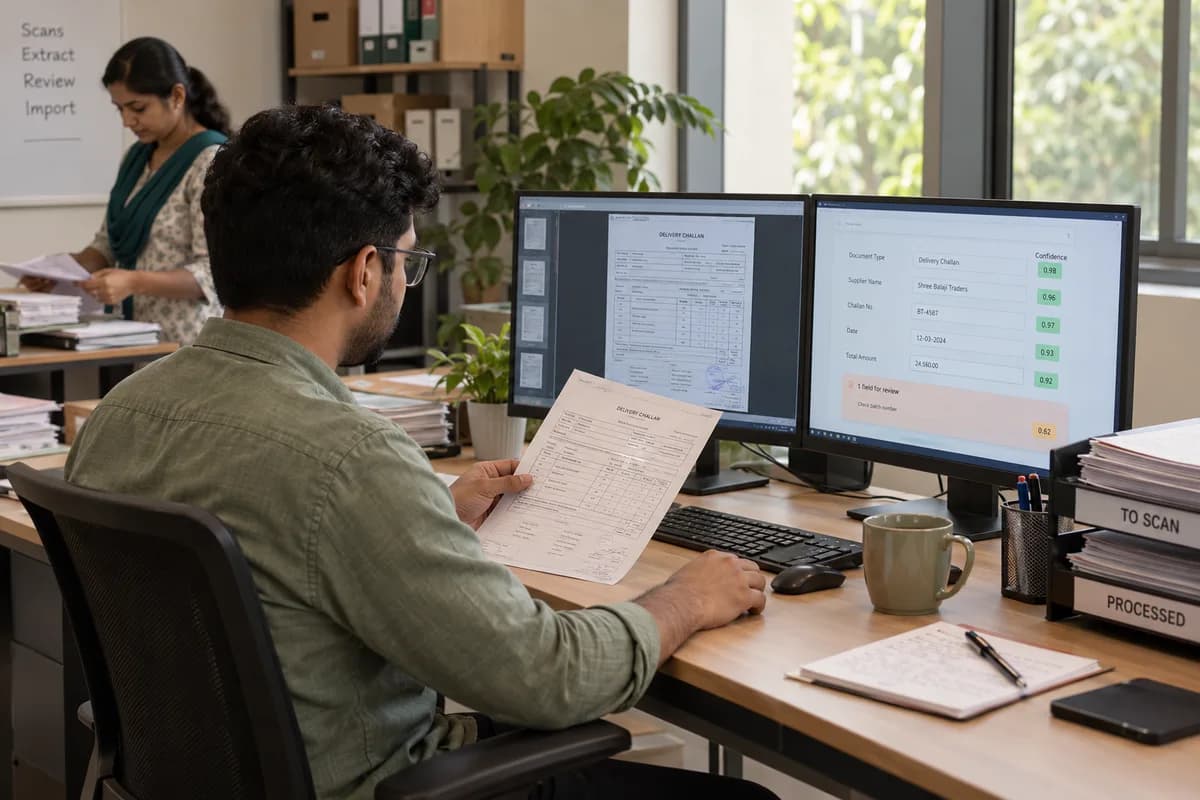
Document intelligence and OCR turn scans and photographs into fields your systems can use. Text is read, the needed fields are identified, and each carries a confidence score so doubtful reads go to a person.
Documents this handles well
- Printed application and KYC forms with a consistent layout
- Delivery notes and goods receipts from regular suppliers
- Identity documents, where the fields sit in known positions
- Contracts and agreements, for pulling out dates, parties and values
- System-generated statements arriving as image-only PDFs
What reads badly
Handwriting reads badly, especially on a delivery note pad. So do photographs taken at an angle with a shadow across the page, faint carbon copies, and stamps or signatures sitting over the figures. Better software does not fix these. The practical answer is usually to improve how documents are captured at the counter.
How fields reach your systems
Read fields are written into your application through an API or an import file, with the original image linked to the record. Anything below the confidence threshold you set is held for review, shown with the field highlighted on the image. A clerk confirms it, and the correction improves later reads.
Frequently asked questions
Can document intelligence read handwritten forms?
Partly, and not well enough to trust without review. Neat block capitals in fixed boxes read acceptably. Running handwriting on a busy delivery note does not, and forcing it through creates more correction work than typing would.
Does this work with documents in languages other than English?
Printed text in major non-Latin scripts can be read, with accuracy varying by script and image quality. A sample of your own documents is tested before any commitment is made.
Will it write into our existing software?
Where that software accepts an API call or an import, yes. Where it does not, fields are delivered as a checked file, which still removes most of the typing.
Who owns the extracted data and the models?
You do. Documents and extracted fields stay in your storage, and any tuning done on your samples belongs to you instead of being added to a shared service.
Tell us what you need.
Share your requirements and one of our engineers will come back to you within one business day.
- No obligation
- A reply within one business day
- Your details stay private
Start with your requirements
Seven short steps that tell us what you need. An engineer reads them before getting in touch.
Share your requirements