In this guide 6 sections
Edge computing processes data on or near the device, while cloud computing sends it to a remote data centre first, which adds a round trip to every decision. The choice is rarely either-or. Most working IoT systems filter and react locally at the edge, then send summaries to the cloud for storage, reporting and cross-site analysis.
What processing at the edge means
Edge computing means the decision logic runs on a local device or gateway sitting close to where the data is produced, such as a controller beside a conveyor. Cloud computing runs the same logic on a remote server, reached over the internet after the data has travelled there, so every decision includes a round trip.
Neither one simply wins. They trade off differently on response speed, dependence on connectivity and how much can be managed from one central place, so ask where each workload belongs. Most real deployments use both.
Comparing latency, connectivity, privacy and maintenance
Edge processing reacts sooner because it skips the round trip to a remote server, and it keeps working when the connection drops, which matters for safety shutoffs. Less raw data leaves the site. That helps with privacy and with a limited mobile data plan at a remote pump station, a farm or a mine, where every uploaded megabyte has a cost.
Cloud processing suits central visibility and scale. It gives one dashboard across every site, software updates pushed from a single place, and enough computing power for analysis that a small local device could never run. The trade-off is dependence on a working connection, plus the job of updating and securing remote devices without ever visiting them in person.
Local filtering and cloud analysis working together
A practical pattern lets the edge device make the fast local decisions, such as stopping a machine, sounding an alarm or rejecting a defective item. Only exceptions travel upward. Reactions stay fast, and a longer-term dataset still builds in the cloud for reporting and trend analysis, without storing every raw reading from every sensor.
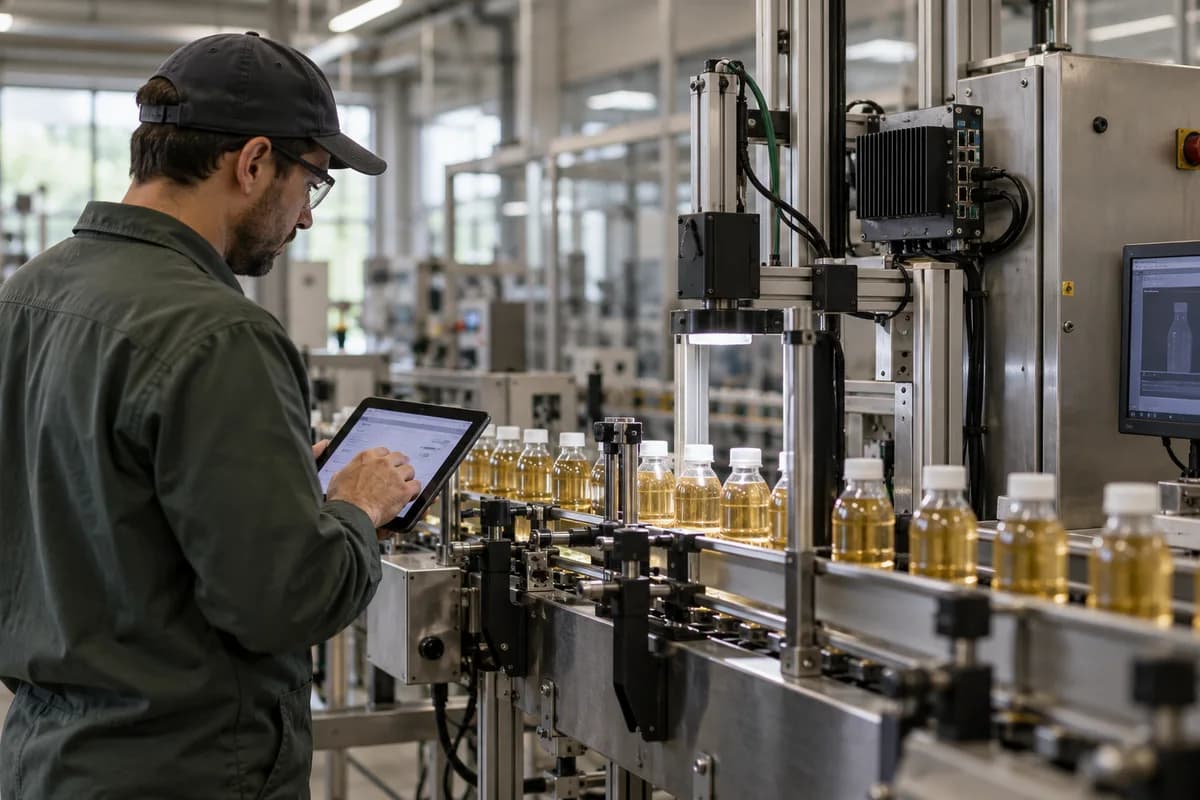
Take a beverage bottling line running a vision check on every bottle, where the reject decision must happen in a fraction of a second on the line itself. No round trip fits in that window. The daily reject rate and its likely causes can be reported and reviewed in the cloud the next morning, when nobody is racing the conveyor.
Hardware support and failure recovery
Edge hardware needs someone who can reach it for updates, repairs or replacement, and it needs a plan for what the equipment does if the local device fails. The machine may keep running unmonitored or fail safe and stop, and you should decide which before the device is installed rather than discovering it during a breakdown.
A cloud dependent system needs an outage plan too, because either local logic keeps a baseline of safety running or the site is effectively unmonitored until connectivity returns. Test both before go-live. Pull the network cable. Power-cycle the edge device. Then watch what each machine does.
Choosing workload placement by operational need
As a rule, anything that must react within a second or two belongs at the edge, and so does anything that must keep functioning when the internet drops. Cross-site views, long-term storage, fleet updates and heavy analysis belong in the cloud, where one team can manage them for every location at once.
Most pilots need not settle this as one architecture decision up front, because the answer is clear once the use case and its response time are written down. Start with one narrow pilot.
Edge-cloud workload comparison
A comparison table listing common workloads down one side: safety shutoffs, defect detection, trend dashboards, cross-site reporting and firmware updates. Each row is marked edge, cloud or both, with a one-line reason for the placement.
Open a blank worksheet to printQuestions owners ask
Can edge devices keep working offline?
Yes, for local logic. Threshold checks, immediate shutoffs and buffered data storage all keep running, while cross-site dashboards and centrally pushed configuration changes wait until connectivity returns.
Do we still need cloud services?
Yes, almost always. The cloud handles long-term storage, reporting across several sites and updates to many edge devices at once, which gets painful by hand as the fleet grows.
Is edge processing always the better choice?
Not at all. A report read once a day gains nothing from local processing, and the extra device still needs power, spares and a person who can reach it for repairs. Keep it for fast decisions.