In this guide 6 sections
AI reads a scanned or photographed invoice, locates fields such as supplier name, tax number and line items, and converts them into data an accounting system can use. Validation rules still matter. Check totals and flag duplicates, because extraction confidence varies with scan quality and layout, and a confident wrong value is worse than a blank.
What OCR does and where a second layer takes over
Optical character recognition, or OCR, turns the pixels of a scanned or photographed document into machine-readable text, and that is the first step rather than the whole job. On its own, OCR cannot tell a tax number from a phone number, or a total from a subtotal, because it sees characters and not meaning on the page. A second layer adds meaning. That layer is usually an AI model trained or prompted to understand invoice structure, and it maps recognised text onto the fields the business needs.
Each layer fails differently. OCR struggles with poor scan quality, skewed photographs and unusual fonts, whereas the field-mapping layer struggles with unfamiliar layouts or ambiguous placement of a number. Knowing which layer failed shows what to fix, whether that is a better scanning routine at the front desk or a wider set of training examples.
Defining the fields needed across every format
List the exact fields first. These might be invoice number, date, supplier tax number, line items, tax breakdown and total, and each one needs real examples in every format it appears in. Take a hypothetical accounts outsourcing firm handling invoices for a dozen client businesses, and expect dozens of different supplier layouts among them. Some are typed and some carry handwritten quantities, and the tax number sits in the header on some and in a footer table on others.
Record where each value came from. Store the page, the client and the original file against every extracted field, so when a number looks wrong later someone can trace it back to the invoice. Never trust a value blindly.
Testing on real documents, not clean samples
The most common mistake in evaluating document AI is testing it on the cleanest, best-scanned invoices available and concluding that it works well. Real accuracy shows up on the messy documents: a crumpled phone photo, a supplier’s handwritten correction, a stamp across the total, and a format the system has never seen. Test on a representative mix.
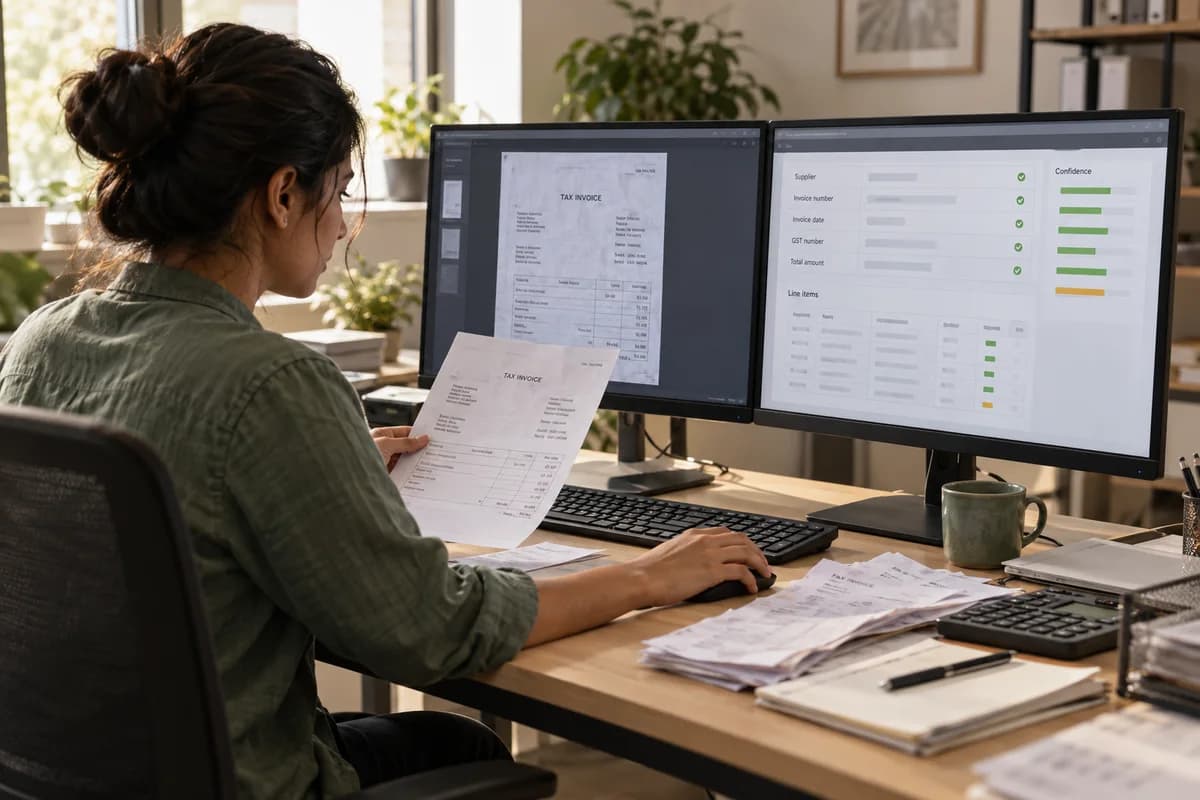
Most extraction systems return a confidence score for each field, not just for the whole document, and that score is worth using. A field extracted at high confidence can usually be accepted without a second look, whereas a low-confidence field should be flagged even on an otherwise clean invoice. Flag the doubtful field.
Catching errors before they become an accounting problem
Extraction accuracy alone does not catch every mistake, because some errors become visible only when business logic is applied on top of the extracted fields. Run three cheap checks. Confirm that line items sum to the stated subtotal, that tax calculations match the stated rate, and that the invoice number has not already been recorded this month.
Duplicates cause double payment. A repeated invoice number is a common source of accidental double payment, and no amount of field-level accuracy will stop it on its own. A system can extract every field correctly and still post a duplicate if nothing compares the new invoice with the ledger entries from last week. These checks are cheap to build.
Routing uncertainty to a person before anything posts
The right default for any low-confidence extraction, unfamiliar format or failed validation check is to hold it for a person to review before it touches the ledger. It converts “AI made a mistake” from a silent accounting error into a quick human check, which is the control that matters most in this kind of system. Hold, do not guess.
For the outsourcing firm, three kinds of invoice wait in a queue for a bookkeeper to review before any of them reaches the general ledger. These are anything below a set confidence threshold, anything from a first-time supplier, and anything whose totals do not reconcile with the stated figures. The clean majority posts straight through.
Document-field-review pipeline
A pipeline diagram in which a scanned invoice passes through OCR, field mapping with per-field confidence, and a validation layer for totals and duplicates. A fork follows, where high-confidence validated records post automatically and everything else routes to a review queue with the original document attached.
Open a blank worksheet to printQuestions owners ask
Can it process handwriting?
To a degree only. Printed and typed text is extracted far more reliably than handwriting, and handwritten figures in particular should be treated as lower confidence. Route them for review rather than trusting them automatically, even when the system returns a value that looks perfectly plausible at first glance.
How should extraction accuracy be measured?
Measure per field, not per document. Calculate how often each individual field, such as total, tax number and date, is extracted correctly across a representative sample of real documents that includes messy ones. A document-level pass rate hides which specific fields need the most review attention, so it makes a poor target for improvement work.
Does it work on documents other than invoices?
Yes, with the same method. Purchase orders, delivery notes, receipts and supplier statements all follow the same pattern of defining fields, testing on real samples, adding validation rules and reviewing doubtful cases. Each needs its own test set.