In this guide 6 sections
A reliable backup plan lists every system worth protecting, sets recovery-time and recovery-point targets, and keeps at least one copy separate from your main environment. Restore drills then prove it. Unrestored backups are untested, not plans. Name one owner and one review date.
Inventory what needs protecting
List every system whose loss would genuinely hurt the business: databases, file stores, configuration, and the accounts and credentials needed to rebuild anything from scratch. Everyone backs up the main database. The small dependencies get forgotten. Examples are an email template store, a crontab on a forgotten server, a payment gateway’s webhook configuration and an integration’s API keys, all of which matter in a recovery.
For each item, record where it lives and who is responsible for it, so nothing depends on one person’s memory or an old spreadsheet of server names. Most gaps come from systems that everyone assumed someone else was backing up, so ask each owner to confirm in writing where the latest copy is stored. Assumptions are not coverage.
Set recovery objectives before choosing a backup tool
Two numbers should drive every backup decision. Recovery Point Objective (RPO) is how much data you can afford to lose, measured as the time between the last good backup and the failure. Recovery Time Objective (RTO) is how long the business can tolerate a system being down while it is restored, counted from the first failed login to the first transaction. Daily backups mean a day of loss. If that is unacceptable, back up more often, since a new tool will not change the arithmetic of how much work happens between two copies.
Ask the business what happens when a full day of transactions disappears and who feels it first, then how long each system may stay down. The business sets targets, not IT. Different systems deserve different targets, because a marketing website tolerates far more loss than an order-processing database ever could, so write each target down per system.
Backups that are separate and protected
A backup stored in the same location, under the same account or with the same credentials as the system it protects is not a real safeguard. It fails against ransomware that encrypts every mounted drive, a compromised admin account, a misconfiguration that deletes data everywhere it has write access, and a single provider outage. One copy must live elsewhere.
Adopt the widely used 3-2-1 rule: three copies of your data, on two kinds of storage, with one copy off-site or in a separate account. Lock the backups against deletion. Amazon S3 Object Lock, Azure immutable blob storage and Google Cloud bucket retention locks all block deletion for a set period, so enable one for critical data.
Rehearse restores and measure how long they take
Unrestored backups are unverified backups. Schedule a restore on a regular cadence into a separate environment, never production, and compare row counts and file checksums against what the system held when the backup ran. Time it against your RTO.
Drills find what reports miss. Jobs may have been failing silently for weeks, a restore may depend on a sysadmin’s laptop or a credential that no longer exists, or it may run far slower. Learn it in a drill.
A first drill can expose an expired storage credential that has stopped the nightly job for weeks while nobody watched the failure notice. Catching that weeks ahead of the annual filing season, when client ledgers are needed under pressure, is the whole point of rehearsing restores on a calendar.
Clear ownership and a review schedule
Name one person responsible for backups running, being monitored and being tested, because “the IT team” as an owner usually means nobody checks until something breaks. Alerts must reach a human. That person should receive an alert the moment a job fails, not discover the gap when a report shows missing data weeks later.
Review it twice a year. Review it again whenever a major system changes, because last year’s plan can quietly stop covering a new database, a new integration or a moved data store. Unreviewed plans decay like unmonitored jobs.
Backup-and-restore test checklist
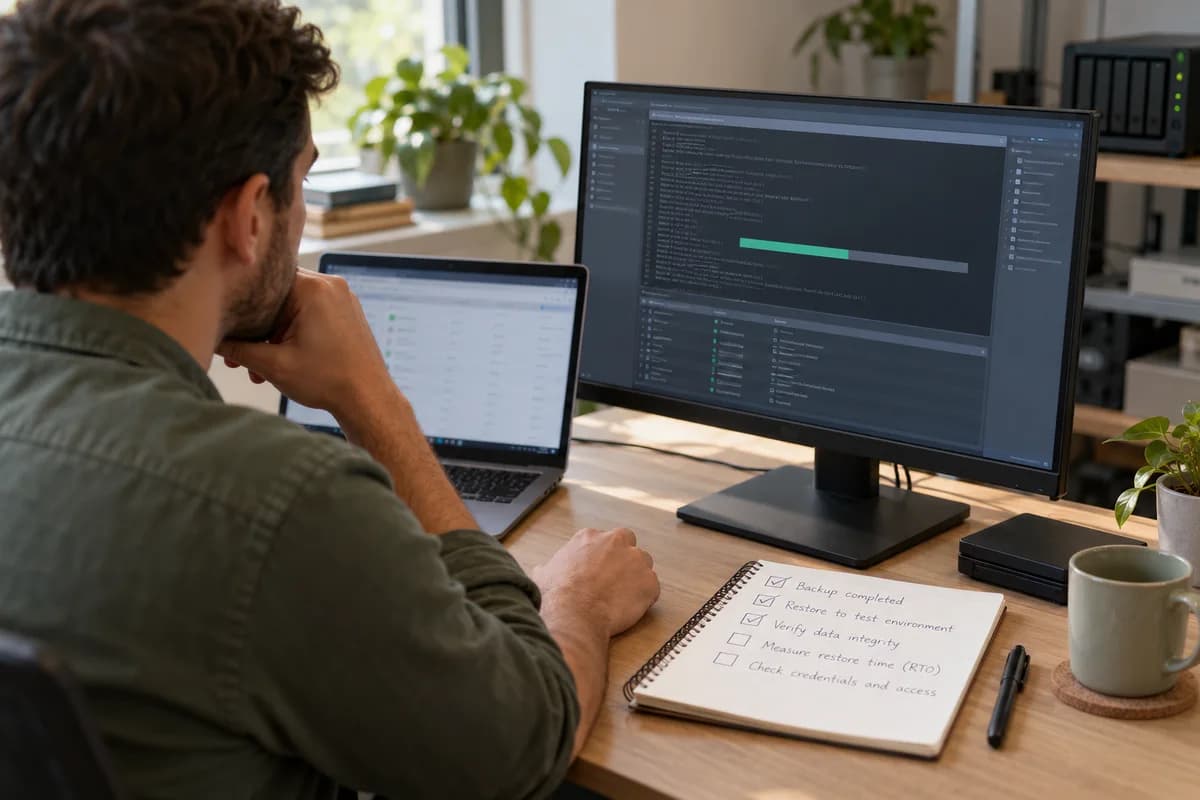
A checklist for each restore drill: the job finished without error, restored data matches a known-good sample, restore time is measured against the RTO, and every credential still works. Run it every time.
Open a blank worksheet to printQuestions owners ask
How do we know a backup works?
Only by restoring from it and checking the result in a real but separate environment, never in production, and by timing how long the restore actually takes. A job that reports success confirms only that the copy process ran, not that the data is complete, correct or restorable within the time your business needs. Put drills in the calendar.
Should configuration be backed up too?
Yes. Application settings, integration credentials, infrastructure definitions and access permissions are often as hard to reconstruct from memory as the data itself, and nobody remembers every setting under pressure. A database restore helps little if the system around it must be rebuilt from scratch by hand, one forgotten setting at a time, while customers wait. Back up configuration too.
How often should we back up?
Back up as often as your recovery point target demands, which in turn depends on how much data the business can afford to re-enter by hand. An order database may need frequent copies through the day, while a rarely edited document store may be fine with a nightly job. Databases with point-in-time recovery, such as PostgreSQL with archived write-ahead logs, can shrink the loss window to minutes, provided someone configures and tests them. Set it per system. Then check that the schedule actually ran.