In this guide 6 sections
CI/CD automates the route from a developer saving a change to that change running in production, with a build, tests and a release artifact produced every time. Integration checks every change. Delivery prepares each passing change for release and leaves the go-live decision to a person, while deployment alone skips that approval and releases automatically.
Continuous integration, delivery and deployment compared
Continuous integration, or CI, means every submitted change is built and tested automatically, instead of waiting for a big batch to be combined, when bugs are hard to trace. CI exposes problems within minutes. Waiting lets conflicts and bugs from different developers pile up until nobody can say which change caused which failure, and the fix then takes days of careful untangling.
Continuous delivery goes one step further and prepares every change that passes CI as a tested, packaged, staged release, while a person still chooses when customers see it. Continuous deployment drops that choice. Anything passing every automated check ships by itself, which suits teams with strong test coverage and a fast way to roll back. Many smaller teams begin with delivery.
How a change moves from code review to a live release
Everything begins with a review. A colleague reads the change, checks it against the team’s standards, and either approves it or asks for edits before anything is merged into the main branch.
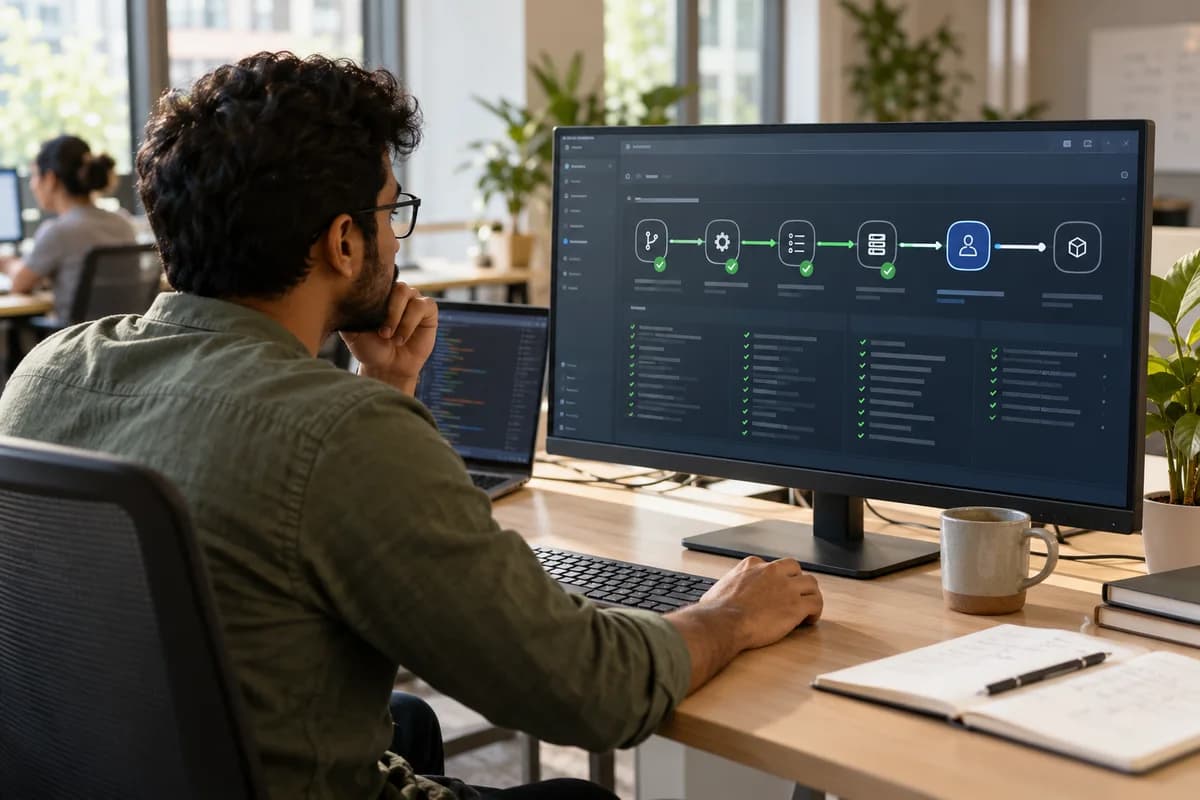
After the merge, the pipeline builds the application and runs linting, unit tests and integration tests, plus smoke checks against a staging environment that mirrors production. A failure stops everything. When every check passes, the change is packaged into a versioned Docker image that either deploys itself under continuous deployment or waits for a named person under continuous delivery. Keep the pipeline log as the record of who approved what, because an audit trail is far easier to read than anyone’s recollection of last Tuesday.
The sequence is identical every time. Compare that with uploading files by FTP to a live server, where every fix is a long run of manual steps that can break something else.
Approvals, secrets and separate environments
Environments must stay separate. Code is tested in a staging environment that resembles production but serves no customers, and only a change that passed there is eligible to reach production. Testing against live data causes avoidable outages. Staging should copy the production setup as closely as budget allows, including the database engine version and the third-party services your checkout calls.
Keep secrets out of code. Database passwords, API keys and payment gateway credentials belong in the secrets manager that every major pipeline platform provides, and using it is a baseline requirement, not an extra. An approval gate names one person who must sign off before production, and it is a control point for higher-risk changes, not a bottleneck to automate away.
Rollback and failure handling as part of the pipeline
Rollback is part of the job. The plan should exist before the change goes live, and ideally redeploying the previous tagged release takes minutes and is as automated as rolling forward. Without that rehearsed path, a failed release turns into an evening of improvised fixes made by tired people who are guessing at the cause.
Failures must be loud. A failed build or failed test should stop the pipeline and notify a named person, never skip the step quietly and carry on towards production. A pipeline that continues past a failed check creates false confidence, which is arguably worse than having no automation at all because nobody thinks to look.
When automation improves release confidence
CI/CD pays back once manual releases are frequent or risky enough to justify building and maintaining a pipeline, because the return comes from avoided mistakes and faster fixes. Weekly shippers benefit quickly. A stable internal tool released twice a year may never repay the effort of building and maintaining a pipeline, test suite and staging server around it. The effort is mostly in the first pipeline, because every later repository can copy its workflow file, its secrets handling and its approval gate.
Look for a repeated pattern. Releases get delayed because they feel risky, bugs trace back to a manual step somebody forgot, or only one person knows how to ship safely. Any one of those is reason enough.
CI/CD pipeline with approval gate
A stage-by-stage diagram covering code review, build, tests, staging, a named approval gate and a production release with an automated rollback path. Compare it with your own process.
Open a blank worksheet to printQuestions owners ask
Does every code change go live automatically?
Only under continuous deployment. Continuous delivery is more common, with automation building, testing and packaging each change while a person decides when it reaches production, keeping a manual checkpoint on customer-facing risk.
How do approvals fit into a pipeline?
They sit right before production. A named person reviews what is about to go live and confirms it, while automation handles the repetitive build and test work up to that point.
Where should secrets be stored?
In the platform’s secrets manager. Passwords and API keys kept there are injected into a build only when needed, so they never appear in the repository or in build logs.