In this guide 6 sections
A working incident-response plan names severity levels and the owner for each, lays out the steps from detection to recovery, and sets who tells staff and customers what. It also records evidence while the incident runs and ends with a blameless review whose fixes have owners and dates.
Incident levels, ownership and escalation defined in advance
Not every problem is the same emergency. Treating a pricing-page typo like a checkout outage burns the urgency you need, so the plan defines minor, major and critical levels with a response time for each.
Each level needs a named incident lead. The role can rotate. The lead coordinates the response, posts the updates and decides when to escalate, instead of personally debugging the fault while ten people wait for news. Without a lead, the person who noticed first ends up directing everything, whether or not they have the access, the calm or the context the job demands.
Detection, triage, containment and recovery as distinct steps
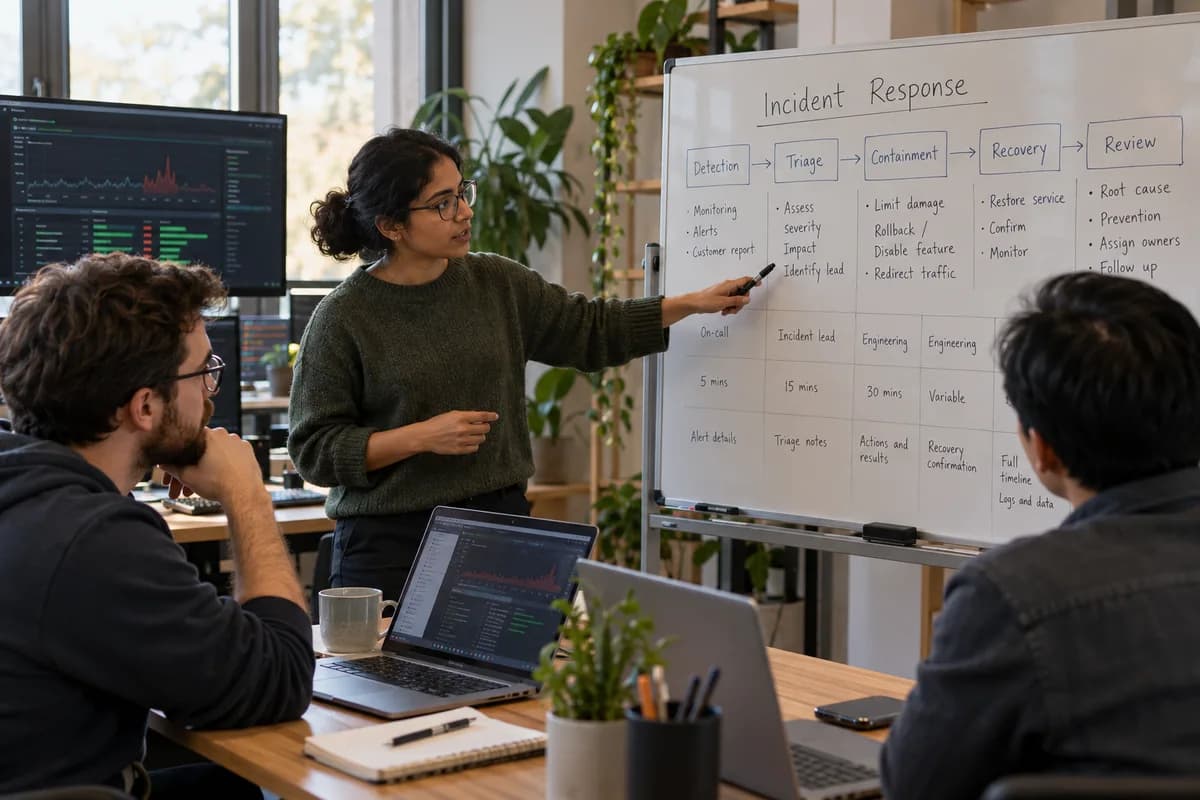
Detection is how the team learns something is wrong, ideally through a monitoring alert on error rates or queue depth, sometimes through a customer email that arrives first. The plan should say what happens next. Triage is a short assessment of severity and affected customers, and a five-minute triage that classifies the incident correctly beats twenty minutes spent debugging the wrong assumption.
Containment stops the damage spreading. It might mean disabling a broken feature, rolling back the latest release or redirecting traffic away from a failing node, all before anyone understands the root cause. List it as its own step. Recovery is restoring confirmed, working service, and a contained incident with degraded checkout or slow pages is not over until recovery is verified.
Communication with internal teams, customers and suppliers
Pick one channel for updates. The lead posts there every thirty minutes, and the plan lists who must be told even if they fix nothing: leadership, customer support and account managers. Nobody gets ambushed by a phone call.
Say what you know. Say what you do not know. A short note naming the affected area, confirming investigation is under way and promising the time of the next update builds more trust than a week of silence.
Vendors matter when the cause sits in a payment gateway or cloud provider, so the plan records who owns each relationship and which escalation number reaches a human.
Evidence and decisions recorded as they happen
Keep a live log. Write down what was observed, what was tried and what changed as it happens, because a log rebuilt from memory is a story, and the review needs facts. It also stops duplicate fixes.
Preserve logs, error messages and monitoring graphs before retention windows overwrite them, especially anything a client contract or compliance requirement might later ask for. Save the evidence early.
Consider a payments startup on a sale weekend where two engineers attack the same checkout failure, each unaware that the other has already changed a setting. The outage runs longer than it should. The fix is easy to find, but nobody holds a shared record of what has already been tried, so each change hides the effect of the last.
Reviewing root causes and following through on fixes
Review every serious incident. A blameless review asks what happened and which conditions allowed it, because people who feel defensive give thinner facts and the fixes that follow are worse.
Cover the timeline, how the incident was detected, what worked in the response, what failed and what would prevent a repeat, then write each prevention action as a ticket. The step most plans skip is follow-through. A review that ends in a list of good intentions with no owner or deadline rarely produces the fix, and the same incident, or a close relative, returns. Check completion at the next monthly meeting.
Incident response timeline and roles
A timeline template that runs from detection through triage, containment, recovery and review. Each stage has a row for the responsible role, the expected time to the next stage and what must be logged. Filled in live, the sheet becomes the evidence record the review needs.
Open a blank worksheet to printQuestions owners ask
Who leads an incident?
A named incident lead. Their job is to coordinate the response and the updates, and naming one for each severity level stops incidents defaulting to whoever noticed first.
How do we communicate when the cause is unknown?
Say what is confirmed. State what is affected, that investigation is under way and when the next update will arrive, and do not wait for a full explanation. Honest uncertainty beats silence.
How soon should we update customers during an outage?
Send the first note quickly. Promise a time for the next update and keep it, with critical incidents needing a message every thirty minutes and minor ones needing a single note at resolution.