Predictive Model Development With Stated Assumptions
Predictive model development builds a model on your own history to answer a specific question, such as which customers may stop ordering. Each result carries its assumptions and its error range.
The question has to be narrow
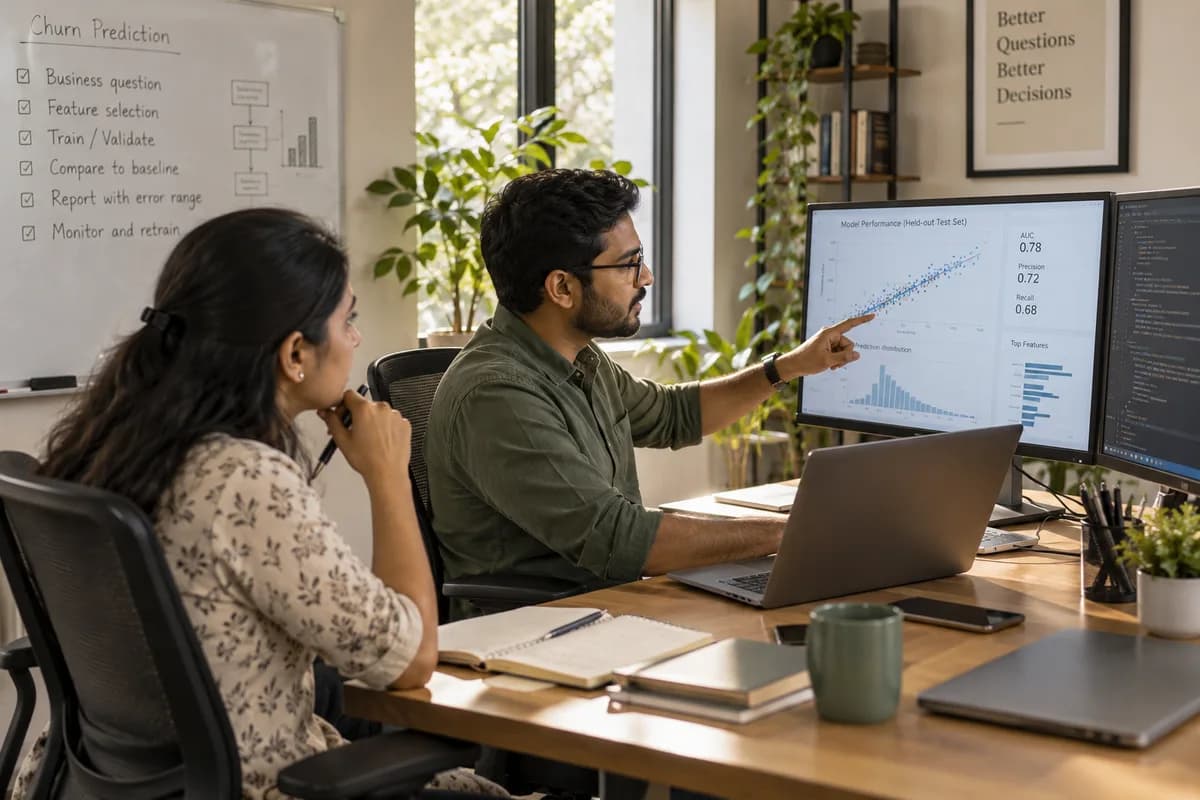
Predict our business is not a question, but predict which active dealers will not place an order next quarter is. A narrow question fixes what to learn from, what counts as right and what somebody will do with the answer. Where that last part is vague, the model is built and never used. It sits idle.
How a model is built and checked
Models go stale
Markets shift, a competitor enters, a product line is dropped. A model trained on last year loses accuracy quietly, and nothing announces it. The checks that compare prediction against outcome are therefore part of the build, with scheduled retraining. Without them, a model is a decaying asset nobody is watching.
Frequently asked questions
How much data does predictive model development need?
Enough examples of the thing being predicted, which matters more than total rows. A few hundred genuine cases of customers lapsing teaches more than a very large volume of routine transactions.
Can a model run against live data?
Yes. It can run on a schedule or through an endpoint your application calls at the moment of decision. Which suits depends on whether anybody acts on the answer immediately.
What if the model turns out to be no better than guessing?
Then we say so and the work stops. That result is useful, because it usually points to a missing field and not a missing model, and collecting that field is the cheaper fix.
Who maintains the model afterwards?
Either your team or ours under a support arrangement. Code, features and training data stay with you, so retraining does not depend on one supplier.
Tell us what you need.
Share your requirements and one of our engineers will come back to you within one business day.
What happens after you share your requirements
- A senior engineer reads your answers. Nobody phones first.
- Within one business day you get a written note: what we understood, what we would start with, and the questions we still have.
- If it fits, a proposal follows with the order of work, what we need from you and what you receive at each step.
- No call is booked and nothing is paid until you have read the note. Your details stay with us.
Start with your requirements
Seven short steps that tell us what you need. A senior engineer reads them before anyone gets in touch.
Share your requirements