Measurement, bottleneck analysis and tuning for websites, portals, APIs and databases
Performance engineering starts with a stopwatch. It measures how long websites, portals, APIs and databases take to respond, then traces each delay to one named query, request or file that costs the time. Changes are made on a staging copy and compared against a baseline recorded on the same test, so the client can check every gain.
- Measurement comes before any change
- Each fix is timed before and after
- Your code, servers and monitoring stay yours
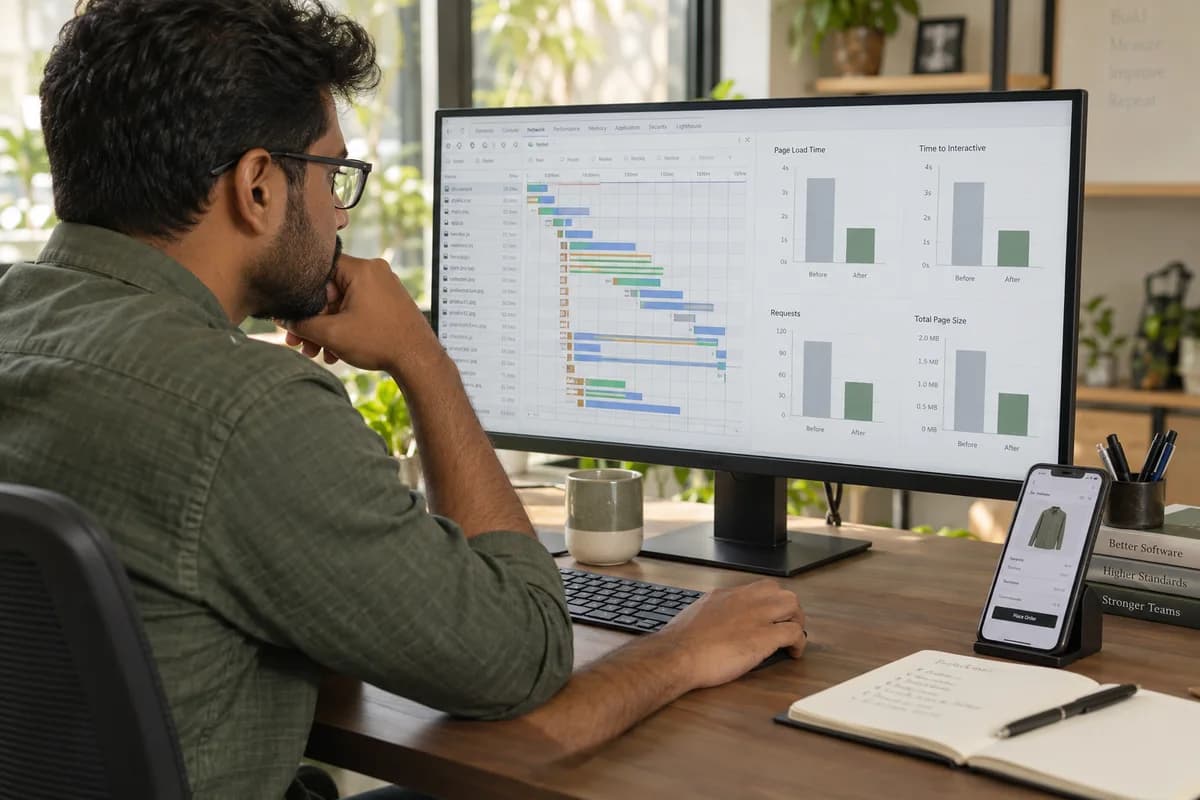
The systems are ordinary ones. Dealer and customer portals, hospital and diagnostic lab systems, school and college ERPs, and D2C storefronts on WooCommerce, Shopify and Magento all turn up. So do custom Laravel, Node or Java applications and reporting dashboards on MySQL, PostgreSQL or SQL Server, each with its own habits of slowing down. Some work is planned ahead of a sale season, an admission cycle or a new large customer, which gives time to measure calmly. Other work starts when a checkout times out and nobody knows why.
Where Slow Software Costs a Business Time
Reports That Are No Longer Run
Six-month sales reports now time out. Staff who once asked for a full ledger or every branch together stopped asking. The report sits in the menu, and the figure it would give exists only in principle. Nobody runs it.
Slowness at Peak Hours
A page that opens quickly for one user slows when a whole branch uses it at once. The morning order rush, payday and month end are typical. Staff refresh and re-enter data that was lost. Duplicates start here.
Unclear Payment Confirmation
After an order is placed, the confirmation screen keeps spinning and the customer cannot tell whether the payment went through. Some customers submit a second order. Others phone the team.
Server Upgrades Without a Measured Result
A larger server was bought to fix slowness. The same screens are slow again. Nothing on record shows whether the first upgrade helped at all, yet a second one is proposed on the same weak basis.
Slowdown as Data Grows
An application that was quick with a few thousand records now holds hundreds of thousands, and list screens that once opened at once now stall work at the counter. The change was gradual. No single day marks it.
No Agreed Cause
The developer points to the hosting, the hosting provider points to the code, and someone else blames the database or the internet line. Each guess costs time and money. The screen is still slow afterwards.
Working Habits Built Around Waiting
Users start a long report and walk off. They keep many tabs open so nothing reloads, or maintain a parallel Excel sheet for one screen, and this quiet waiting is rarely counted anywhere in the business.
Slowness is measurable. It is a quantity of time spent in one query, one request or one file download, and it can be written down in seconds. Until someone measures it, every fix is a guess.
Measure First, Then Change the Slow Part
We instrument the application and watch it closely during the hours it struggles. Then we record where the time goes, whether that is a request, a query, an image, a queue or a payment gateway call. Fixes are made on a safe copy and compared on a test that can be run again, and each release carries a way to keep watching.
Baseline Before Changes
Current behaviour is recorded on the chosen screens, at the hours that matter, on the devices customers actually hold, and a target is agreed for each journey. Nothing is tuned first.
Evidence for Each Finding
Request traces, slow query logs and browser timings name each bottleneck in plain terms, and the client sees the same evidence we do. Fixes worth funding are chosen from it. The rest wait.
Changes That Hold as Data Grows
Indexes, query rewrites, caching with clear expiry rules, pagination and background jobs are chosen for the data volume the system will reach, not today’s. The aim is a system that stays quick across seasons, and not one that merely looks good the week after the change.
What Changes After Performance Work
Focus on business value before discussing technology.
Bottlenecks Identified and Ranked
Each bottleneck is written down with the measurement behind it, in order of the time it costs, so opinion between developer, host and team no longer decides the cause. The numbers do.
Work Aimed at Revenue Journeys
Effort goes to search, cart, payment, booking and login. Screens where nobody waits are left alone.
Peak Load Tested in Advance
Sale weekends, results days and season openings are simulated on a copy of the system beforehand, so what fails first is found and fixed before live traffic arrives. Not during it.
More Work From the Same Server
A query that reads less data and a page that requests fewer files lower the load on the machine you already pay for. Capacity is added for real growth. It no longer absorbs wasted work.
Before and After on the Same Test
The same test is repeated after the changes. Both sets of numbers go to the client.
Gradual Slowdown Visible on a Graph
Response time, error rate and query duration are charted week on week, so a slow decline shows up while it is still small and cheap to correct.
What Performance Engineering Covers
Everything required from operational discovery to production deployment and long-term maintenance.
Performance Audit and Baseline
The journeys that matter are measured under real conditions. The baseline records response times, slow queries, page weight and the hours at which each journey worsens, so later claims have something fixed to be compared against.
Bottleneck Analysis
Requests are traced through the application, the database and every external service they call, and the time spent is pinned to a named cause. No guessing.
Database and Query Tuning
We read slow query logs and execution plans, then design indexes and rewrite queries, and repeated lookups inside loops are removed. Tables that have outgrown what any screen needs get an archiving rule, so that list pages open quickly again.
Backend and API Optimisation
Code paths that dominate a request are reworked through connection pooling, batching, pagination and streaming for large exports, and report generation and bulk messaging move into background jobs. The user stops waiting.
Frontend and Core Web Vitals
Image sizing and compression, script and style trimming, font loading, lazy loading below the fold and layout stability are the work. It targets the metrics Google records on real visitors.
Caching and Redis
Application, query and page caching come with a written rule for what expires when, so a price change or stock movement is never served from a stale copy.
CDN and Asset Delivery
Images, scripts and downloads are served from edge locations close to the customer. Compression and cache headers are tuned for mobile connections outside major cities, where every megabyte is felt.
Load and Stress Testing
Peak traffic is simulated on a staging copy, with scripts written against real journeys such as login, search, cart, checkout and reports. The test shows where the system bends. It also shows what bends first.
Checkout and Critical Journey Tuning
This is focused work on the sequence that carries revenue: cart, payment gateway callback, order confirmation and the messages that follow. It also covers a slow gateway.
Infrastructure and Cost Right-Sizing
Server, database and storage sizes are set from the load the system actually generates, which is often lower than the current instance suggests. Load balancing and scaling rules go in where the constraint sits. Sizing follows evidence.
Mobile and Low-Bandwidth Performance
We test on mid-range Android phones and throttled connections. A page judged on an office laptop says little about how it opens for a dealer or a patient on a phone.
Monitoring, Alerting and Capacity Planning
Dashboards show response time, throughput, error rate and database load, with an alert threshold set against each one. A written view of remaining headroom says how much room is left before the next upgrade is due, so planning replaces panic.
Where Performance Work Is Used
Real-world business processes we configure and automate.
D2C Store With a Slow Payment Step
A clothing brand sends campaign traffic to its store and finds the payment step is the slowest part of the visit on its busiest days. Measurement shows two causes. The cart re-checks stock for every item whenever a quantity changes. Product photographs reach phones at full size. Both are corrected. The journey is timed again to confirm the gain.
Distributor With a Congested Order Screen
Dealers place orders in the same two-hour window each morning, and order entry is slow only then. Tracing shows an availability lookup running once per row instead of once per page, at the very hour a long accounts report hits the same database. The lookup is rewritten. Reporting moves.
Pathology Chain With Wide Date Ranges
Referring doctors view patient reports on the lab’s portal. As years of records piled up, queries spanning more than a month stopped returning, and the support desk went back to emailing PDFs. The fix is index design, pagination and an archiving rule for older results. Reports return.
College Group With Result Day Traffic
The student portal is quiet most of the year. On results day, and again on the last date for fee payment, students and parents arrive within the same hour. The result screen rebuilt the same answer from several tables for every visitor. It is now computed once at publication, receipt generation moves to a queue, and both journeys are load tested before the next cycle arrives.
SaaS Product With One Large Tenant
A subscription platform signs a large client, and smaller customers then report slowness. The cause is shared database contention. One tenant’s heavy reports block everyone else’s ordinary work, and query tuning, read separation for reporting and per-tenant limits address it without separate servers.
Courier Network With a Polled Tracking Endpoint
Client systems poll the operator’s tracking endpoint continuously, and in the holiday season those calls time out. Measurement finds the same lookups repeated for the same consignments, with no caching and no pacing. Status is now cached. Eager callers are slowed. Writes are queued.
Is This Service Right for Your Business?
We partner with established businesses that have outgrown manual processes and want reliable systems.
Businesses With a Slow Customer Step
Online stores, booking systems and customer portals where visitors drop off at search, cart, payment or login, and support keeps hearing that the site hung.
Companies Whose System Slowed as Data Grew
Internal applications and ERPs that ran well at launch and now struggle with lists, searches and reports because far more records sit behind the same screens.
Organisations Heading Into a Known Peak
A seasonal sale, an admission or results window, a year-end close, a marketing campaign or a large customer going live. The load is predictable. It can be tested beforehand.
SaaS and Multi-Tenant Platform Operators
Product companies adding customers onto shared infrastructure, where one heavy account can degrade the experience of every other tenant on the same database.
Businesses With Rising Hosting Cost
Companies that have upgraded servers more than once. They want to know whether the next upgrade is truly needed or whether the software is wasting the capacity it already has.
Cases Where Performance Work Is Not the Right Step
If a small site is slow because of the cheapest shared hosting plan, changing the plan costs less than an engagement, and we say so. If the problem is wrong results rather than slow ones, that is testing work. If the system is due for replacement within a few months, the findings can be kept and applied to the new build.
Enterprise Capabilities in Plain Business Terms
Request Tracing
A single slow request is broken into application time, database time, external calls and waiting, so the largest share stands out at once. That is where work begins.
Slow Query Log Analysis
Database logs are collected over real working hours and grouped by total time consumed, not only by the single worst example.
Execution Plan Review
The plan shows how the database resolves a query. An index is added because the plan calls for it, never on a hunch, and the plan is kept as evidence.
Repeated Query Detection
This finds screens that fire hundreds of near-identical queries, a common cause of a list page that will not open.
Caching With Expiry Rules
Values that rarely change are cached, and written rules state what must never be cached, such as stock, price and balance. Expiry is explicit.
Background Job Offloading
Report generation, bulk messaging, invoice PDFs and exports move out of the user’s request, so the screen returns at once. The work finishes behind it.
Pagination and Streaming
Large lists and exports are delivered in pages or streamed in parts, so hundreds of thousands of rows are never assembled in memory before anything appears on screen. Nothing hangs.
Asset and Image Optimisation
Correct dimensions, modern formats, compression and lazy loading mean a product page stops downloading several megabytes that a phone never displays.
Connection and Pool Tuning
Database connections, worker counts and timeouts are set to match real concurrency, so requests queue in order instead of all failing together.
Rate Limiting and Back-Pressure
These controls stop one heavy caller, crawler or runaway script from consuming the capacity that paying users need.
Real-User and Synthetic Monitoring
Measurement from visitor devices sits alongside scheduled synthetic checks. The team sees what customers experience, and no longer only what the office network shows.
Reusable Load Test Scripts
Peak traffic tests are handed over as scripts the client keeps, so the same journeys can be re-run before each release or season. Nothing is locked away.
Our Structured 6-Step Delivery Process
A transparent path from your first conversation to a reliable production release.
- 01
Symptom Discovery
We speak with the people who feel the slowness and record the specific screens, the times of day and the workarounds. From the client we need that list in the team’s own words, plus one person who can reproduce the problem and say which journeys matter to the business.
- 02
Baseline Measurement and Instrumentation
Monitoring goes on. The slow query log goes on. Behaviour is then recorded over normal and peak hours. We need read access to the application, database and hosting, plus permission to install monitoring for the duration and a window for a short restart if required.
- 03
Bottleneck Report and Prioritised Plan
Findings arrive in order of the time each one costs, with the measurement, the effort to fix and the risk. The client chooses the priority journeys and agrees a target for each one, because a checkout and a monthly report need different standards.
- 04
Optimisation on a Safe Copy
Changes are made and measured on a staging copy, never first in production. We need a staging environment or permission to build one from a recent backup. We also need a decision-maker who can approve code changes, and a contact at the existing vendor where they own part of the code.
- 05
Load Testing and Controlled Release
Peak traffic is simulated on the copy, and the improvement is confirmed on the same test as the baseline. Release follows in an agreed window, rollback ready. The client nominates users to verify the live result and approves that window. Then we watch.
- 06
Monitoring, Handover and Capacity Plan
Dashboards, alerts, test scripts, the before-and-after comparison and a capacity view are handed over, and the capacity view shows the room left before the next upgrade. The client names a person to receive alerts. Whether monitoring continues with us is its decision.
What You Receive Upon Project Completion
Everything required to run, maintain, and expand your software without vendor lock-in.
Connects With the Systems You Already Rely On
We build bridges between your software so you don't have to replace functional existing tools.
Application Platforms
- Laravel and PHP applications
- Node.js and NestJS
- Django and Python
- Java and Spring
- .NET applications
Web and Commerce
- Next.js and React
- WordPress and WooCommerce
- Shopify storefronts
- Magento
- Custom portals and dashboards
Databases
- MySQL and MariaDB
- PostgreSQL
- Microsoft SQL Server
- MongoDB
- Redis
Hosting, Cloud and Delivery
- AWS
- Azure
- Google Cloud
- DigitalOcean
- Shared and managed hosting
- On-premise servers
- Cloudflare
- CDN edge caching
- Nginx and Apache tuning
- Varnish
- Object storage for media
Payments and External Services
- Payment gateway callbacks
- WhatsApp and SMS providers
- Courier and logistics APIs
- Third-party lookup services
Selected for Reliability, Speed, and Longevity
Technology chosen to match your operational scale and long-term maintainability.
Measurement and Tracing
Load and Stress Testing
Database Analysis
Dashboards and Alerts
Caching, Delivery and Infrastructure
Why Business Owners Choose GullySystem
Measurement Before a Fix Is Quoted
An audit shows what is wrong before anyone commits to a rebuild, and many slow systems have two or three causes carrying most of the time. Finding them early keeps the work small. Rebuilds are rarely needed.
No Direct Changes in Production
Optimisation is done on a copy and measured there. It reaches the live system through an agreed release window with a rollback prepared, so your working day is never the test environment.
Larger Servers Recommended When Measurement Supports It
Sometimes the finding is that the code is reasonable and the machine is undersized, or that the hosting plan is the whole problem. We report that plainly. Weeks of tuning around it would waste your money.
The Same Test Before and After
The same journeys run under the same load, before and after, so the client can verify the result without trusting our word. That is the proof.
Work on Code Built by Others
Most of this work is on applications built by another team or vendor, and we read the code as it stands. Where the existing vendor remains involved they are kept informed, and changes are handed back in a form they can maintain.
Measurement Setup Handed Over
Dashboards, alerts and load test scripts stay with the client, and the same tests can be re-run before the next release or season. Nothing is held back.
Flexible Engagement Options
Choose an engagement model that matches your operational scope, budget, and timeline.
Performance Audit
A bounded engagement produces the baseline, the bottleneck report and the prioritised plan, and the client then decides what to fix, in what order, and who does it. No code changes.
Targeted Optimisation
Work on the single screen or flow that costs the most, such as the checkout, the order list or a month-end report. It runs against an agreed target. A before-and-after comparison closes it.
Peak Readiness
Load testing and hardening before a sale season, an admission window, a campaign or a large customer going live, with the scaling plan written down in advance.
Ongoing Performance Support
Continuous monitoring, periodic re-measurement and tuning follow as record counts and user numbers rise. Degradation is caught early. It stays small.
Frequently Asked Questions
Straightforward answers to the questions owners ask before getting started.
What exactly is performance engineering?
It is the work of measuring how long software takes to respond, finding the specific causes of delay and removing them. It covers the browser, application code, database, network and servers together, because a slow screen is usually the sum of several small delays. Rarely is it one broken component.
How do you identify the actual bottleneck?
By measurement. Tracing is attached to the application, so a slow request splits into application time, database time, external calls and waiting. The database slow query log is collected over real working hours and queries are ranked by total time consumed, while browser behaviour on the page is recorded too. The bottleneck becomes a named query, function or file. It carries a number.
Will you make changes directly on our live system?
No. Measurement can run on production because it is read-only and light on overhead, but changes are made and proved on a staging copy first. The release then happens in a window you approve, with a rollback prepared and someone from your side available to verify. If a copy cannot be created, we say so before work starts and agree a narrower approach.
Can you tune software that another company built?
Yes, and that is most of this work. The original team is not required. We need source code, database access and hosting access. An existing vendor stays informed. Changes are handed over in the structure they maintain. Everything we write goes into your repository. It is yours.
Does this improve Core Web Vitals and our Google ranking?
It improves Core Web Vitals, which measure loading, responsiveness and layout stability on real visitor devices, and search engines weigh those as one input among many. Faster pages help but do not replace strong content. The clearer gain is commercial: fewer visitors abandon a slow page, especially on mobile.
Can you test peak traffic without risking real customers?
Yes. Load test scripts are written against your real journeys, such as login, search, cart, checkout and reports. They run at rising concurrency against a staging copy that mirrors production, and the test shows what bends first, whether the database, the web server or an external service. Tests on production run only in a quiet window.
Will this reduce our cloud or hosting bill?
It can, but only measurement sets a figure. When a query reads less data or a page downloads fewer files, the same machine handles more work, which can delay the next upgrade or allow a smaller size. Sometimes the server is simply undersized. Then the advice is to spend on infrastructure.
What if the finding is that the system needs rebuilding?
Then we say so and show the evidence. It does not become an open-ended project. Some systems are slow for structural reasons that tuning cannot fix beyond a point. The audit still shows which parts must be redesigned and which can be carried across. It gives the replacement a measured target.
What drives the cost of software performance optimisation?
It depends on how much of the system must be examined and changed. Scope is set by the number of journeys, whether source code and database access are available, how the application is built, and whether the slowness sits in one place. Load testing and later monitoring also count. An audit is priced separately. A firm figure follows scoping.
What decides how long it takes?
It depends on access and reproduction. Code, database and hosting access must arrive first, and if the slowness appears only at certain hours, we have to wait to measure it. A staging copy may exist. It may need building. The number of separate causes, changes needed from a third-party vendor and the observation period after release also play a part. A timeline is confirmed after scoping.
How is our data protected while you measure?
Work is done with accounts issued in your name, limited to what the task needs, over encrypted connections. Staging copies with masked or reduced data are preferred for testing. Monitoring records timings and query shapes, never customer records. Confidentiality is signed before discovery. You can revoke any access we hold.
What happens after the optimisation? Will it slow down again?
It can, as data and users grow. For that reason the engagement ends with monitoring. You receive dashboards, alert thresholds, the load test scripts and a capacity view of the headroom that remains. Re-running those tests before a major release catches the next problem early. Ongoing monitoring with us is a light arrangement.
Can a caching plugin or CDN fix our slow site instead of a performance engagement?
Sometimes. For a simple problem, a CDN for static images or a caching plugin can fix a slow marketing site or blog, and that is worth trying first. These tools stop helping once the slowness is inside the application code. Examples include a query that scans too much data, a report that recalculates on every load and a checkout that waits on an external service. Those need the time traced to its source.
Read before you decide.
Practical notes on the questions this service raises, not product marketing.
How to Evaluate Whether Your Software Can Scale
How to test whether your business software will hold up under growth, before a busy season or expansion finds out for you, using real peak numbers.
How to Find the Reason Your Business Application Is Slow
A method for diagnosing a slow business app: reproducing the issue, measuring each layer, and finding the real bottleneck before spending on fixes.
Website Performance Audit Checklist
A practical checklist for auditing a business website’s speed: pages to test, what to measure, what to inspect, and how to prioritise fixes.
How Database Performance Affects Application Speed
Why a slow database is often the real cause behind a slow application, and how queries, indexes, locks and data growth drive it.
Let’s Build the Right Software for Your Business
Tell us about your current operational challenge, spreadsheet bottleneck, or software requirement. An experienced engineer will review your workflow and reply within one business day.
- No obligation consultation
- Senior engineer reviews your brief
- Your operational details stay 100% confidential
Start with your requirements
Seven short steps that tell us what you need. An engineer reads them before getting in touch.
Share your requirementsRelated Practices & Services
Cloud and Managed Infrastructure
When the measurement shows the servers, storage or scaling setup itself needs redesigning rather than the code.
DevOps, Deployment and Reliability
Release pipelines, environments and uptime practices so improvements reach production safely and repeatedly.
QA and Software Testing
Functional and regression testing for the times the problem is wrong output rather than slow output.
Software Maintenance, Support and Rescue
Ongoing care for an application you inherited or that has been left without a development team.