Cloud hosting, migration, monitoring, backups and cost control for the servers and databases that business applications run on
Cloud engineering and managed infrastructure covers the servers, databases and storage that business applications run on, from assessment and migration to monitoring, restore-tested backups, a security baseline and costing. It suits small and mid-size businesses and SaaS companies that have no infrastructure engineer on staff.
- Cloud account, domain and keys registered in the client’s name
- Backups checked by an actual restore
- Alerts routed to a named person with a written runbook
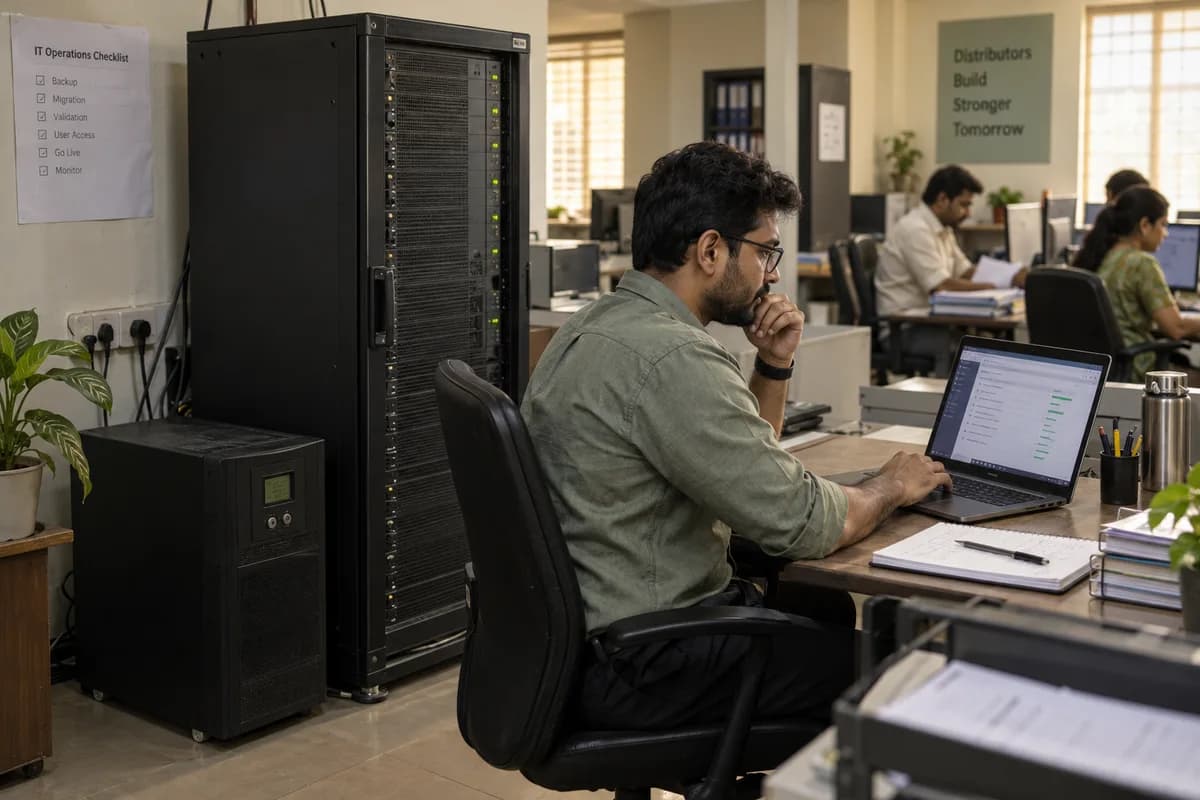
Real cases look like this. A billing application sits on a tower PC beside the accounts desk. A SaaS product runs on one cloud server, and a distributor watches its invoice climb while the software stays unchanged. A diagnostic lab keeps scan reports for years. Some projects are a first move. Others inherit an environment from a departed vendor, with no diagram, no working alert, no restore ever attempted and a backup nobody has opened.
Where Unmonitored Infrastructure Causes Problems
Everything on One Machine
One office tower or one cloud server holds the application, the database and the backup copy. A failed disk or a long power cut then stops billing, dispatch and customer enquiries together, because there is no second machine ready to take over the work. Everything halts at once.
Backups That Were Never Restored
The backup job reports success every night, so nobody ever opens the copy. It may be months old, may omit the uploads folder where scans and attachments live, or may sit on the very machine that failed with it. Nobody knows. A backup nobody has restored is only a hope.
A Cloud Bill Without Line-Item Detail
The invoice rises quarter after quarter while order volume stays flat. Nobody can tell the production database from a test server made for an experiment and never switched off, so the bill is simply paid and the question is postponed.
Accounts Held in Someone Else’s Name
The hosting account was opened with a former developer’s email address and is paid on a vendor’s card that the finance team has never seen. The invoice, the domain and the certificate renewals all sit outside the business, beyond the owner’s reach. Adding a user means a favour from someone gone.
Full Disks and Failing Writes
Log files, old exports and uploaded images slowly eat the free space on a single server, and the machine is never suspected. Screens still load. Then invoices stop saving and attachments fail, because no alert was watching free space and nobody had been told to check it.
Storage With No Retention Rule
Scan images, attachments, exports and transaction history pile up because nothing is archived and no retention rule is written down. The nightly backup now runs into the working day, and a restore would take longer than the business can pause. Storage on the bill grows by default.
Expired Certificates and Domains
An SSL certificate lapses because a renewal notice landed in a mailbox nobody opens. Customers meet a browser warning and orders stop until the certificate is replaced, which is a quick fix once someone notices. Rebuilding trust is slow.
None of this needs a software rewrite. It needs a hosting environment sized for the load it carries, a monitor watching disk, memory and certificates around the clock, and a backup restored at least once. The bill should also read line by line.
Infrastructure Designed Once and Then Operated
GullySystem takes responsibility for where the applications run. We begin by reviewing the current setup, then propose an environment sized to real usage and budget, and rehearse the move with a defined way back. After that, operations cover monitoring, patching, backups, restore drills, certificate renewals and monthly cost reporting, so the midnight emergency becomes a rare event that has a written procedure. Planned work replaces panic.
Sized for Measured Usage
We measure the users, orders and reports the system handles in its busiest hour, then build for that with headroom. Capacity follows real usage. Nobody picks a specification for show.
Recovery Tested in Advance
We restore backups into a separate environment on a schedule and time every restore. The business learns in advance how many hours of data and how many working hours a failure would cost, and that figure is written down.
A Named Person on Every Alert
Uptime, disk, memory, error rates and certificate expiry are checked around the clock, and each alert reaches a named person together with a written instruction for the first step. It never sits on a dashboard.
What Changes When Someone Owns the Infrastructure
Focus on business value before discussing technology.
Backups Restored on a Schedule
We rehearse recovery by restoring into a scratch environment and timing the result. The data loss and downtime a failure would cause become agreed figures, signed off by the owners and written down well before any failure happens. Surprises are removed in advance, not discovered at midnight.
Alerts for Exhaustion and Expiry
Free disk, memory, database connections, queue depth and certificate expiry dates are tracked continuously, and each one raises a named alert before it becomes an outage. Nothing waits for a customer complaint. Nobody finds out from a phone call.
A Cloud Bill Mapped to Systems
Every resource carries a purpose tag. The business can see what production costs, what testing costs and which resources run for no system at all, so idle spend gets a name and an owner.
Every Alert Type Has an Instruction
Each alert type has a runbook entry covering what it means, what to check first and whom to call, with an architecture diagram and an access register beside it. The person on call follows a written procedure.
Accounts and Keys in the Client’s Name
The cloud account, domain, certificates and credentials belong to the business, while GullySystem access is scoped and can be revoked at any time. Changing the operator becomes a planned decision. It is never a rescue.
A Written Recovery Route
A failed region, a deleted database, a ransomware incident or a dead server each has an agreed recovery route, an order of steps and a responsible person. Corporate customers and auditors often ask to see exactly this document, so we write it once and keep it current.
What Cloud Engineering and Managed Infrastructure Covers
Everything required from operational discovery to production deployment and long-term maintenance.
Infrastructure Assessment and Architecture
We review current servers, hosting, costs, backups, access and single points of failure. The result is a target architecture sized to real traffic, accepted risk and a stated budget. A prioritised risk list comes with it. Nothing is built yet.
Cloud and Server Migration
Applications, databases and uploaded files move from an office machine, shared hosting or another provider, and we rehearse the whole move on a copy first. The cut-over has a defined rollback point. A failed attempt costs nothing permanent.
Managed Cloud and Application Hosting
We own the daily running of the environment, which covers patching, capacity, certificate renewals, maintenance windows and incident response, and a monthly report lists uptime, changes and spend. Application code stays with your developers.
Server and Database Administration
This covers user and permission management, storage growth, replicas, index and vacuum routines and version upgrade planning, which together keep the database healthy. Databases need regular housekeeping to stay fast and intact, and neglect shows up first as slow month-end reports and invoices that take a full minute to save. We schedule that work. It never becomes a weekend surprise.
Monitoring, Uptime and Log Management
External uptime checks, resource metrics, application error tracking and centralised logs are set up together, so a question about last Tuesday evening has a recorded answer. Nobody has to guess what happened. The evidence is already stored.
Alerting and Escalation Setup
We confirm alert thresholds with the customer when the work is scoped, and notifications go to email, WhatsApp or a chat channel. An escalation order passes the alert to a second contact, and then a third, whenever the first person does not acknowledge it within the agreed interval. Each alert type has a runbook entry.
Backup and Restoration Testing
We set backup schedules, off-site and cross-region copies, and retention rules that match the client’s record-keeping duties, and periodic restores into a separate environment are recorded with their timings. The proof exists on paper. A job log alone is not proof.
Disaster Recovery and High Availability
Recovery targets are stated in plain terms: how much data can be lost and how long the system can stay down. Options include a standby route, load balancing across redundant servers, database failover with a replica, and a second region for the systems where a day of downtime is unacceptable. Each one is included only where the business case pays for it.
Infrastructure as Code and Repeatable Builds
Servers, networks and services are defined in version-controlled scripts. An environment can then be rebuilt or duplicated on purpose, instead of being assembled by hand from memory, and the scripts double as living documentation of what exists. Drift is easy to spot.
Cloud Security Baseline
At the infrastructure layer we set up private networks, firewall and access rules, multi-factor authentication on every console login and least-privilege accounts for each person and each service. A patch policy completes the baseline. Application code review is separate.
Cost Review and Spend Control
We tag resources, right-size instances, move cold data to cheaper storage tiers and apply committed-use or reserved capacity where usage is steady. Idle resources and old snapshots are removed. Budget alerts arrive before the invoice does.
DNS, Domain and SSL Management
A register lists every domain and DNS record. Certificates renew automatically where the provider allows it. SPF, DKIM and DMARC records support delivery of transactional email, and a content delivery network is configured where it cuts load and latency.
Where Managed Infrastructure Is Used
Real-world business processes we configure and automate.
Distributor Moving Off an Office Server
A distributor runs billing and stock software on a tower PC in the accounts area, and a power cut stops invoicing at every branch. We size a cloud environment for the number of concurrent billing counters at the busiest branch, then rehearse the whole move on a copy of the database. The database moves in an agreed quiet window, and staff then open the same screens from a hosted address with off-site backups behind them.
SaaS Company Handing Off Hosting
A small product team loses evenings to restarting services, clearing disks and renewing certificates, and database upgrades fall on weekends. We take over the environment, with patching in agreed windows, monitoring with an escalation route, and backups with restore drills. A monthly report covers uptime, incidents and spend. Release pipelines are separate work.
Diagnostic Lab Chain With Long-Term Records
Patient reports and scan images pile up on one server, with a spare copy on an external hard disk kept by a branch manager. We separate storage from compute. Older records move to archival storage under a written retention rule, an encrypted copy is kept in a second location, and a sample report is restored every quarter.
Manufacturer Reviewing a Rising Cloud Bill
Order volumes are flat, yet the monthly invoice keeps rising after an undocumented vendor-led migration, which nobody can explain. We tag every resource to a purpose and list the oversized databases, duplicate test environments and old snapshots, then right-size production to measured need. Budget alerts flag the next jump the same week.
Training Institute Preparing for Enrolment Day
On results and enrolment days a training institute’s site receives a month of normal traffic within a few hours. We place the application behind a load balancer and a CDN, scale compute up for the day and bring it down afterwards, and rehearse the peak against a copy. A status page stays live. Slow application code is separate work.
Logistics Operator Documenting Recovery
A transport company bidding for corporate contracts is asked how quickly it could recover from a total failure, and cannot answer. We document the architecture, agree recovery targets with the operations head, build a standby environment in a second region and run a live failover on a chosen Sunday. The auditor gets a drill record.
Is This Service Right for Your Business?
We partner with established businesses that have outgrown manual processes and want reliable systems.
Businesses Running on an Office Machine
Companies whose billing, stock or operations software lives on an office PC or a small server kept under a desk or in a storeroom. They depend on the building’s power, the internet link and one person who knows how to restart it. That is a fragile chain.
Product and SaaS Companies Without an Infrastructure Engineer
Software teams that can build the product well but lose hours every month to servers, full disks, database upgrades and expiring certificates. They need someone to own the environment. Engineering time then returns to features and releases.
Companies With an Inherited Setup
Businesses whose infrastructure was built by a developer who has since left or by a vendor who is no longer engaged, and who left nothing behind in writing. There is no diagram and no documented access, and nobody can say what each server does or which can safely be switched off.
Businesses With an Unexplained Cloud Bill
Organisations paying a monthly cloud invoice that keeps rising without any matching rise in orders, users or revenue, and that nobody on the team can read line by line. Nobody inside can map a line item to a system, so every renewal is approved on trust and every increase is simply absorbed.
Businesses With Recovery Obligations
Clinics, labs, financial services firms, schools and suppliers to large corporates, all of which keep records retrievable for a defined period or answer tender questions about continuity and recovery.
When Managed Infrastructure Is Not Needed
A brochure website on shared hosting gains little from this service, nor does a business that runs wholly on a managed platform where the vendor handles servers and backups. A team with a capable system administrator may need only a one-time assessment and a restore drill. Even then, the drill is worth running. We say so plainly.
Enterprise Capabilities in Plain Business Terms
Uptime and Health Checks
External checks run from outside the client’s network and confirm that the application itself answers, not merely that the server has power. Power reaching the server is not proof. A login page that loads is proof.
Resource and Capacity Metrics
CPU, memory, disk, connection and queue trends are kept over many months, and each is plotted against the number of users at that hour. Growth becomes visible long before it turns into an outage, and every capacity request arrives with a graph attached. Guesswork drops out of the conversation.
Centralised Log Collection
Application, web server and system logs are gathered in one searchable place, and the client chooses the retention period. A failed payment from last Friday can be traced without logging in to each server in turn. Search replaces guesswork.
Alert Routing and Escalation
Thresholds are agreed with the client, and notifications go to email, WhatsApp or a Slack or Teams channel. A second contact is alerted when the first does not acknowledge within the agreed interval, so a missed phone never means a missed outage.
Automated Backup Schedules
Database, file and full-system backups run on a defined schedule, and copies are held away from the machine they came from, in object storage or a second location. A copy on the same disk does not count.
Periodic Restore Drills
Scheduled restores run in an isolated environment. Each one is timed and recorded. Recovery becomes a rehearsed procedure and never a first attempt made under pressure at night, with the owner watching over your shoulder.
Patch and Maintenance Windows
Operating system, runtime and database updates are applied in agreed windows, and each update is tested on staging before it reaches production. Staff hear about the window beforehand. Nobody is surprised by a restart.
Access Control and Multi-Factor Login
Named accounts carry least-privilege roles, and the cloud console requires multi-factor authentication for every login, including ours. An access register is reviewed on a schedule, and leavers lose access on the day they leave, while shared logins are retired. Nobody keeps a key by habit.
Network and Firewall Rules
Databases sit on private networks. Remote access goes through a VPN or bastion host, so no port is left open for convenience. Exposure is kept as small as the application allows.
Certificate and DNS Register
Every domain, DNS record and certificate is documented with its expiry date, and renewal is automatic where the provider allows it. A manual renewal gets an owner and a reminder. Nothing lapses in silence.
Scaling and Right-Sizing
Capacity is raised for known peaks such as enrolment day or a holiday sale and reduced the day after. Instance sizes are reviewed against measured usage every month, so the business stops paying for headroom it no longer needs.
Budget Alerts and Cost Reports
Spend is tracked against a monthly ceiling, with an alert when a threshold is crossed. A report attributes cost to each system, so production, testing and idle resources are separated. The finance head can read it unaided.
Our Structured 6-Step Delivery Process
A transparent path from your first conversation to a reliable production release.
- 01
Infrastructure Discovery and Access Review
We list every server, service, domain, certificate and cloud account the business depends on, with the cost and risk against each. We also note what would stop if any one failed. Read access to the cloud console or servers, recent hosting invoices and the person who last made a change all come from the client.
- 02
Target Architecture and Recovery Targets
We propose the environment: sizing, network layout, backup schedule and retention period, with acceptable data loss and downtime set for each system. The client supplies the busiest hours, the systems that cannot stop in working hours, record-retention duties and a budget ceiling. Nothing is built until the client signs off.
- 03
Environment Build and Security Baseline
Networks, servers, databases, storage, monitoring and access rules are created and defined in version-controlled scripts, so the environment can be rebuilt from them. The client opens the cloud, domain and certificate accounts in the business name and approves who gets which level of access.
- 04
Migration or Deployment Rehearsal
Data is copied into the new environment and run alongside the existing one, and we rehearse the whole cut-over with a defined rollback point. The client nominates users who check their own screens, reports and printing on the copy, and agrees the maintenance window with staff and customers.
- 05
Go-Live, Monitoring and Backup Verification
We switch over, watch the system closely through the first working days, and tune capacity against the real load of staff, customers and overnight batch jobs. The backup is then restored into a separate environment with the client present. Acceptance is confirmed against the checks agreed in step two. That includes a restore the client has seen complete.
- 06
Handover, Runbook and Ongoing Operations
The handover includes the architecture diagram, access register, scripts, cost report and a runbook covering each alert, and the person who will receive alerts is trained. The client names that person and an escalation contact, and decides whether GullySystem continues monthly operations or moves to advisory support.
What You Receive Upon Project Completion
Everything required to run, maintain, and expand your software without vendor lock-in.
Connects With the Systems You Already Rely On
We build bridges between your software so you don't have to replace functional existing tools.
Cloud Platforms
- Amazon Web Services
- Microsoft Azure
- Google Cloud
- DigitalOcean
- Existing VPS and colocation providers
Monitoring, Alerting and Delivery
- Uptime and status checks
- Prometheus and Grafana
- CloudWatch and provider monitoring
- Sentry error tracking
- On-call escalation tools
- Email, SMS and WhatsApp Business API alerts
- Slack and Microsoft Teams channels
Backup and Storage
- Object storage and S3-compatible buckets
- Snapshot schedules
- Cross-region and off-site copies
- Archival storage tiers
Databases
- PostgreSQL
- MySQL and MariaDB
- MongoDB
- Redis
- Managed database services
Network, Domains and Security
- Cloudflare
- Load balancers and reverse proxies
- VPN and bastion access
- Let’s Encrypt and commercial SSL
- Domain registrars
Selected for Reliability, Speed, and Longevity
Technology chosen to match your operational scale and long-term maintainability.
Cloud, Compute and Containers
Infrastructure as Code
Monitoring and Logging
Data and Storage
Network and Delivery
Why Business Owners Choose GullySystem
Backups Are Restored Before They Count
A backup that has never been restored is an untested assumption. We restore into a separate environment, time it, record the result and keep the log. The recovery position then becomes a documented fact that a corporate customer, a tender committee or an external auditor can inspect for themselves at any time.
Sizing Follows Measured Traffic
We measure the busiest hour before specifying anything. A smaller environment that can grow beats a large one billed every month for capacity nobody uses, and right-sizing therefore starts before the first server is created. Measurement comes first.
Cost Is Part of the Design
Cost is a design constraint, discussed at the architecture stage and not after the first invoice arrives, because instance sizes and storage tiers are chosen then. Every resource is tagged from the start. Spend stays a decision the client makes, with the numbers in front of them.
Changing Operators Is Planned, Not a Rescue
Cloud accounts, domains, certificates and credentials are created under the client’s own business, with GullySystem access scoped and revocable. Leaving us is a planned decision. It never turns into a rescue.
Documented for Any Engineer to Take Over
The client receives diagrams, an access register, environment scripts and a runbook, so another engineer can pick up the infrastructure without contacting us. That is the practical test of a handover. We apply it to ourselves.
Working Alongside the Existing Team
Existing developers or the current vendor keep the application, and we take the environment underneath it. Who touches what is agreed in writing. During an incident, nobody waits for another party to answer a phone call. The roles are already defined.
Flexible Engagement Options
Choose an engagement model that matches your operational scope, budget, and timeline.
Infrastructure Assessment
We examine current servers, hosting costs, backups, access and failure points, and the client receives a prioritised risk list and a target architecture. The assessment stands alone, with no obligation to continue.
Migration or Build Project
A bounded piece of work, such as moving off an office server or another provider, or building a new production environment. It is priced against an approved architecture and written acceptance checks, and it ends at the agreed cut-over, after which the client decides on operations.
Managed Hosting and Operations
We run the environment. That means monitoring, patching, backups, restore drills, certificate and DNS management, incident response, and capacity and cost reporting, with response terms set in an agreed arrangement.
Infrastructure Takeover
This suits an inherited or undocumented environment. We regain and secure access, document what exists and close the immediate risks, such as an open database port or an expiring certificate. Advice on what to rebuild comes afterwards.
Frequently Asked Questions
Straightforward answers to the questions owners ask before getting started.
Do we need managed cloud infrastructure, or is our current hosting fine?
That depends on the cost of an outage and on who fixes it today. We ask both. An application that serves a few internal users, or one on a managed platform where the vendor handles servers, backups and updates, is probably adequately hosted. This service suits applications that take orders, issue invoices, hold patient or student records or serve paying customers, where nobody currently watches, patches or tests recovery. If your setup is adequate, we say so.
Which cloud provider is right for us: AWS, Azure, Google Cloud or something simpler?
It depends on the workload, existing licences and team. AWS, Azure and Google Cloud offer the widest managed services and multi-region options, and they suit larger or regulated workloads. DigitalOcean and similar providers are simpler and often cheaper for a single application with predictable load, which describes many small business systems. Microsoft licensing, a need to keep data in a particular region, a specific managed database or existing credits can each decide it. The reasoning is written down during assessment. The build happens in the client’s account.
Can you migrate our application to the cloud without a long shutdown?
Yes, in most cases. The new environment is stood up beside the old one and the data is copied across. Both run in parallel. Then the team rehearses the cut-over on a duplicate while your own staff look on. The switch is planned for the quietest window, with a rollback point agreed in advance. The length of the window depends on database size, how much data changes during the copy, whether the application can run read-only for a period, and DNS propagation. We measure these in the rehearsal. You see the numbers before a date is fixed.
Are the backups actually tested, or only configured?
They are restored, timed and recorded on a schedule. Configuring a backup is only the first half. The second half is proving the copy can be brought back into a working system, so we restore into an isolated environment and check the data is complete. We confirm the application runs against it and note the restore time. That shows what a real failure would cost.
What does managed hosting include, and what is outside it?
It covers the environment, not the application. Included are monitoring and alerting, operating system and database patching, capacity and scaling, backups with restore drills, certificate and DNS management, security baseline upkeep and incident response. A monthly report covers uptime, changes and spend. New features, bugs in application code and design changes sit outside, as development work for the client’s team, an existing vendor or GullySystem under a separate arrangement. The boundary goes in writing.
We already have developers or a vendor maintaining our application. Do you take over from them?
No. We take the environment underneath, not the application. Developers or the existing vendor continue with features and fixes in the codebase, while we own the servers, backups, monitoring and everything else the code depends on. Both sides agree in writing who touches what. Nobody phones a developer about a full disk.
Who responds when something breaks at night?
A named person, following a written runbook. Alerts route to whoever is on duty, with the affected system, the symptom and the first steps attached, under a response arrangement agreed at sign-up. Covered hours, response times and the failures that justify a call-out are set with the client in advance. A stopped payment flow gets a faster response than a slow report page does. The escalation path is shared with your team.
How is security handled at the infrastructure level?
By shrinking what is exposed. Databases sit on private networks, administrative ports are closed to the public internet, and remote access goes through a VPN or bastion host. Accounts are named and least-privilege, with multi-factor authentication on the cloud console and a short list of people who can create new access. Secrets live outside the code and can be rotated, patches are applied in agreed windows, and access and audit logs are retained. Code vulnerabilities, penetration testing and secure development are a separate discipline, handled in a separate engagement. We say so when that is the need.
Will our cloud bill come down?
It can. We state no figure before reviewing the account. Every resource is tagged to a purpose and reported. Common sources of savings are oversized instances, test and staging environments left running overnight, old snapshots, unattached storage volumes, unexamined data transfer and steady workloads paying on-demand rates. Some businesses are under-provisioned and should spend more. We report what we find either way.
What drives the cost of this work?
Two separate things drive it. One is our work. The other is the cloud bill. Proposals keep them apart. Our effort depends on the systems in scope, on whether the build is fresh or an undocumented setup must be untangled, and on the state of the data. Strict recovery targets add effort, because a standby region costs more than nightly backups, and so do scripted automation and full monthly operations. Cloud spend follows traffic, data volume, retention period and the level of redundancy the business chooses to buy. We confirm cost after assessment.
What decides how long it takes?
Access, data volume and rehearsal, more than the build. The main factors are how quickly cloud, domain and vendor accounts are opened in the client’s name, and how large the database and file store are. Others are whether the application needs changes to run in a new environment and how many people verify their screens before cut-over. The parallel-run period and the maintenance windows the business can offer also matter. Discovery turns these inputs into a dated schedule.
Do we own the cloud account, the configuration and the scripts?
Yes, all three. The cloud account, domain and certificates are registered to the client’s business and billed to it. GullySystem access is a scoped role. It can be revoked at any time. Terraform and Ansible files, configuration, monitoring definitions and runbooks are delivered into the client’s own repository, so another engineer can rebuild the environment without our involvement. Nothing runs inside a GullySystem account. Nothing depends on our continued involvement.
What do you need from us, and will you train our team?
Yes to training. Every handover includes a runbook and a session. From the client we need read access to current servers or the cloud console, recent hosting invoices, and one person who can authorise account creation and access decisions. An operations person names the systems that cannot stop, and when. The person who will receive alerts and read the monthly report is trained in plain language, and the runbook covers what each alert means and what to do first.
Read before you decide.
Practical notes on the questions this service raises, not product marketing.
When Should a Business Move Its Software to the Cloud?
A practical way to decide if cloud migration solves a real problem for your business, or if your current setup is already good enough.
Cloud Migration Checklist for SMBs
A phase-by-phase checklist for moving business software to the cloud without losing data, missing a scheduled job or extending downtime.
AWS vs Azure vs Google Cloud for Small Businesses
How to choose between AWS, Azure and Google Cloud based on your workload, existing tools and team skills, not brand reputation.
How to Control Unexpected Cloud Costs
Why cloud bills spike unexpectedly, and a practical process for finding, controlling and preventing overspend without cutting reliability.
Let’s Build the Right Software for Your Business
Tell us about your current operational challenge, spreadsheet bottleneck, or software requirement. An experienced engineer will review your workflow and reply within one business day.
- No obligation consultation
- Senior engineer reviews your brief
- Your operational details stay 100% confidential
Start with your requirements
Seven short steps that tell us what you need. An engineer reads them before getting in touch.
Share your requirementsRelated Practices & Services
DevOps and Deployment Reliability
Release pipelines, automated testing gates and safe deployments, layered on top of the infrastructure we build and run for you.
Cybersecurity and Application Security
Application-level security review, vulnerability testing and hardening for the software that runs on your environment, which is a separate discipline.
Performance Engineering
When capacity is not the problem, we profile and tune the application and database so pages and reports return faster.
Software Maintenance and Support
Ongoing fixes, upgrades and small improvements to the application itself, working alongside the infrastructure that hosts it day to day.